August 29, 2026
Open Weights Shift AI Economics
Low-cost open-weights models running on Chinese infrastructure now match US frontier capabilities at pennies on the dollar, disrupting reliance on a...
Created by Jaime S
Latest AI models, benchmarks, algorithms, and applications across robotics, healthcare, coding
Explore the latest content tracked by AI Innovation Radar
Low-cost open-weights models running on Chinese infrastructure now match US frontier capabilities at pennies on the dollar, disrupting reliance on a...
Embodied AI lacks trustworthy benchmarks, but RoboColiseum delivers a high-fidelity simulation platform where the sim-to-real gap stays below 10%. It...
Anthropic's Model Hardware Standard (MHS) gives AI agents a direct interface to control lab instruments and close the physical feedback loop, marking...
Google’s new Gemini 3.5 Transcribe splits into two distinct endpoints that force real architectural choices for voice interfaces.
The real breakthrough behind Microduck isn't the robot—it's the full pipeline: MuJoCo simulation with PPO and GPU training, followed by ONNX export to turn learned locomotion into deployable behavior.
Google DeepMind ran the first double-blind evaluation of a proprietary frontier model by loading Gemini 2.5 Flash Lite weights and confidential...
Amazon Biodiscovery ran an agentic protein design experiment focused on antibodies that received far less attention than Anthropic's version. This...
Can tabular foundation models truly replace task-specific training? The 2026 guide highlights models that predict directly on new data with zero...
GlucoFM shows how dual-stream modeling and self-supervised pretraining can convert abundant unlabeled CGM traces into reusable embeddings for clinical...
Skild AI's S1 model learns 10-minute tasks like pancake flipping from one human video, hitting 66% success on unseen tasks versus 9% for...
Apodex-1.1-mini-FP8 delivers competitive frontier performance in a compact FP8-quantized vision-language model, scoring 50.2 on FrontierFinance and...
Two studies expose how easily safety protections fail in production AI setups.
Nvidia's SONIC delivers whole-body control through a single foundation model trained on 100M+ motion frames, enabling real-time adaptation across...
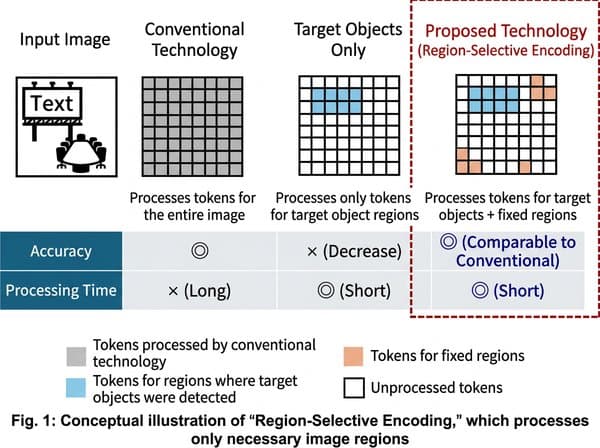
Hitachi's selective region encoding limits Vision Transformer computation to object regions and fixed attention spots, halving average...
Aftab, a composite CNN encoder for Parallelized Q-Networks, achieves a 0.86 Probability of Improvement over standard PQN baselines on Atari-57 with an...
SWE Refactor Bench shows current evaluations fail for codebase migrations by allowing agents to pass tests without actual changes.
Boehringer Ingelheim's Mol-JEPA learns jointly from 14 modalities—structure, cell painting (CLOOME), binding affinity (Boltz-2), ADMET, DFT, and...
Reasoning models' self-correction, hypothesis testing, and hedging across thousands of tokens show no link to correct answers. Accuracy stays strong regardless of these visible behaviors.