3h ago
TRACE Shows Gains in Inpatient Risk Prediction via Daily Trajectories
TRACE organizes multimodal events into day-level trajectories using temporal attention and phenotype-guided contrastive learning, achieving highest...
Created by GrowthMasters Team
A content tracker sharing interesting discoveries
Explore the latest content tracked by 4MINDS || AI Production Readiness & Continuous Learning Radar
TRACE organizes multimodal events into day-level trajectories using temporal attention and phenotype-guided contrastive learning, achieving highest...
Can AI models truly translate plant electrical signals into reliable grower actions?
Cloud providers now see Anthropic as a competitor, not just a customer, making it harder to secure enough capacity despite plans to spend over $750...
Community-driven open math models are now essential because big tech tools no longer reliably serve mathematicians, and only community governance can ensure AI aligns with the field's needs and retains domain ownership.
LLMs remove critical source context that humans use to spot bias or fabrication, turning deliberately planted false statistics into seemingly...
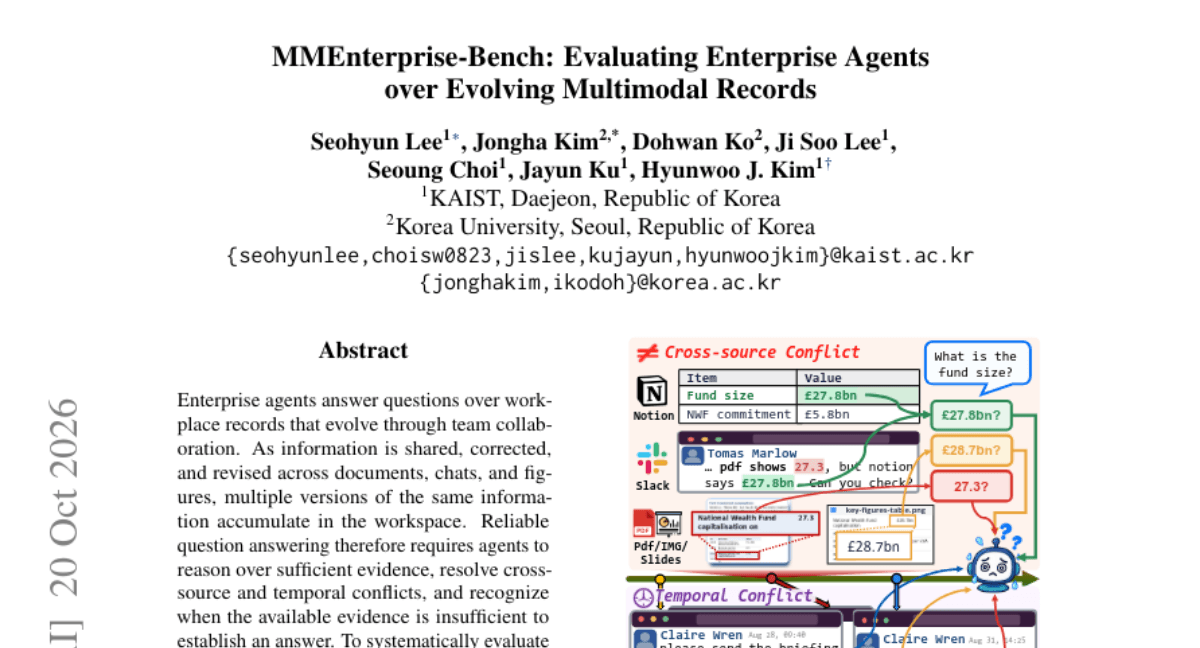
Enterprise agents must handle evolving workplace records with conflicting versions across chats, documents, and images—not just static facts....
Tenstorrent raised $1.5 billion at a $6.2 billion valuation to scale inference chips for open-weight models and video generation. After its Galaxy...
A guardrail verdict only blocks harm if enforced before or during the model or agent action.
NVIDIA's decode-specialized kernels in Cute DSL deliver 423 tok/s/user on the 2.8T Kimi K3 model through a vLLM optimization, yielding 1.68x faster inference on identical hardware.
Dream Labs launched a robot foundation model API at $0.75–$3/hour after raising $90M, but real capability remains limited.
What does Terminal Bench 4 saturation mean for measuring genuine agent progress?
Most benchmarks test against synthetic assumptions that break on uncaptured edge cases in real deployment. EgoTac delivers grounded signals by...
AI agents designed to shop and transact autonomously are hitting hard barriers from Amazon, eBay, JPMorgan, and others. Platforms cite security risks,...
How will Anthropic measure the governance and real-world impact of its new public benefit fund?
Recursive self-improvement research for terminal agents is highlighted as essential reading for anyone tracking training of terminal or coding agents.
LLM analyzed 150k Reddit posts to identify side effects of an unapproved new GLP-1 drug, surfacing early candidate signals from patient discussions before any clinical validation.
Learned orchestration in multi-agent systems promises flexible coordination without fixed patterns, yet papers expose hidden failure modes like belief...
Can an AI agent safely suggest IaC fixes for cloud architectures?
Anthropic's proposed bill activates only after 50 deaths or $1B damages, prompting claims it targets open-weight models rather than managing real...