5h ago
Gemma 4 E2B: Bedrock access vs early local decision-model claim
Two deployment paths emerge for Gemma 4 E2B.
- Bedrock path: Catalog availability confirmed in us-east-1/2, us-west-2, eu-central-1 at $0.04/$0.08...
Created by Peter Felber
Latest open-source LLM releases, benchmarks, and deployment guides for 32‑64 GB VRAM setups
Explore the latest content tracked by Open LLM Deploy
Two deployment paths emerge for Gemma 4 E2B.
Inception positions Mercury 3 as proof diffusion LLMs scale like autoregressive ones, claiming 1,068 tokens per second, 4-8x faster inference, and...
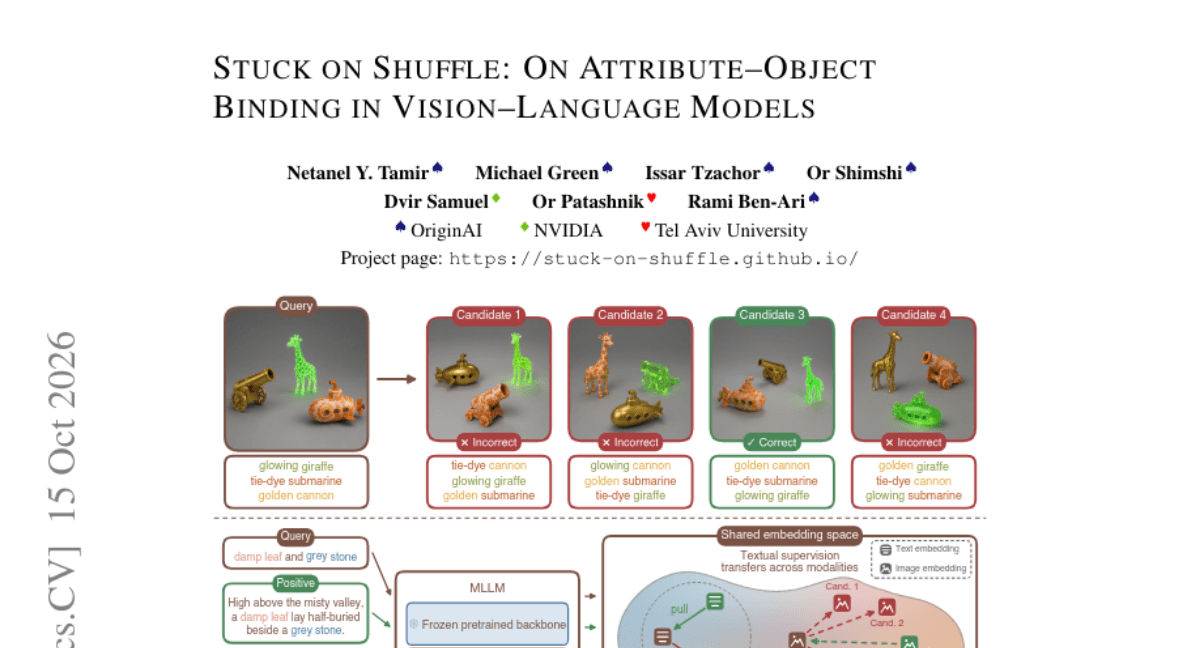
If a vision-language model retrieves images with the correct objects but swaps their attributes, results become unreliable in real queries.
Key...
Open-weight models can lose safety safeguards after fine-tuning, quantization, or config changes even while maintaining task performance. Microsoft...
Most speculative decoding methods assume stable contexts and maintain growing KV caches, leading to up to 80% acceptance length drops in long,...
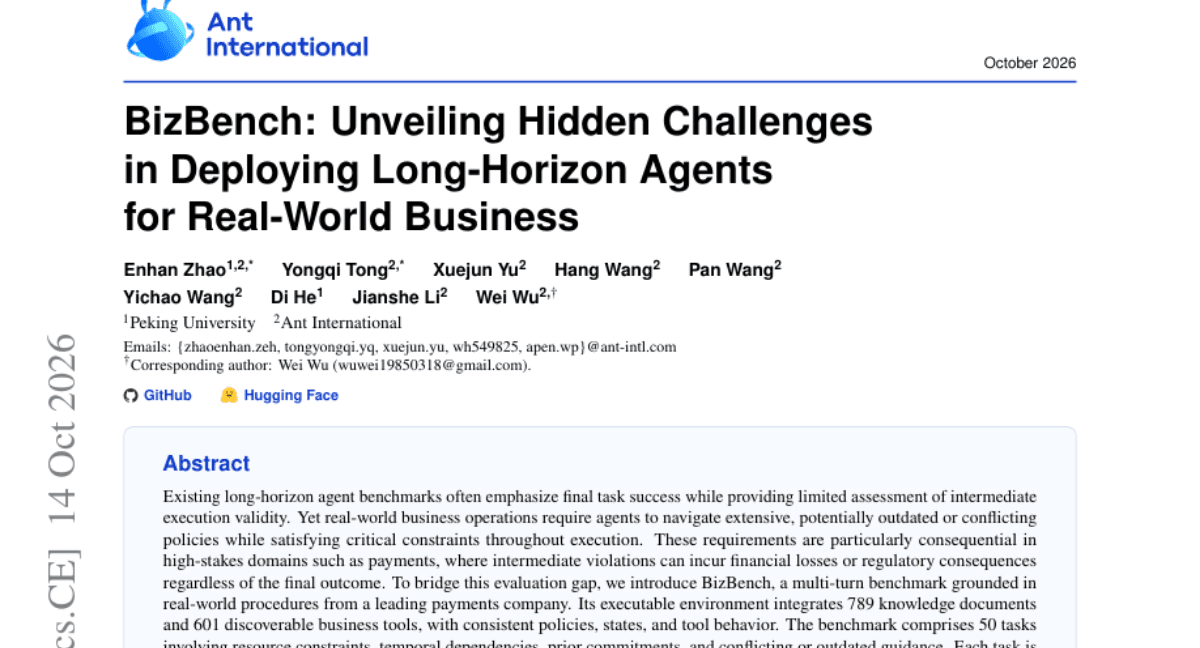
Standard benchmarks track only final task success, overlooking intermediate policy violations that can trigger real financial or regulatory costs in...
Ollama hit 100% success in 15 trials with a 1.83-second median TTFT, a promising deployment signal for low-latency setups. The limited sample size means comparable tests across tools are still needed.
DeepSeek calls its new open-source DeepSeek-V4.1-Flash-1017 faster and leaner, citing stronger benchmark results in reasoning, coding, and agentic...
No shared public benchmarks exist for coding between Intern-Decision-4B and Qwen3.5 Plus, so the comparison names no winner. All category rows stay not comparable with zero matched results.
An 8B reasoning model generates multiple research ideas in one generation from source papers, trained with a reward that scores the full set for both...
Coding agents like Codex now handle full self-hosting workflows—from organizing media and installing Jellyfin to connecting Node-RED with Home...
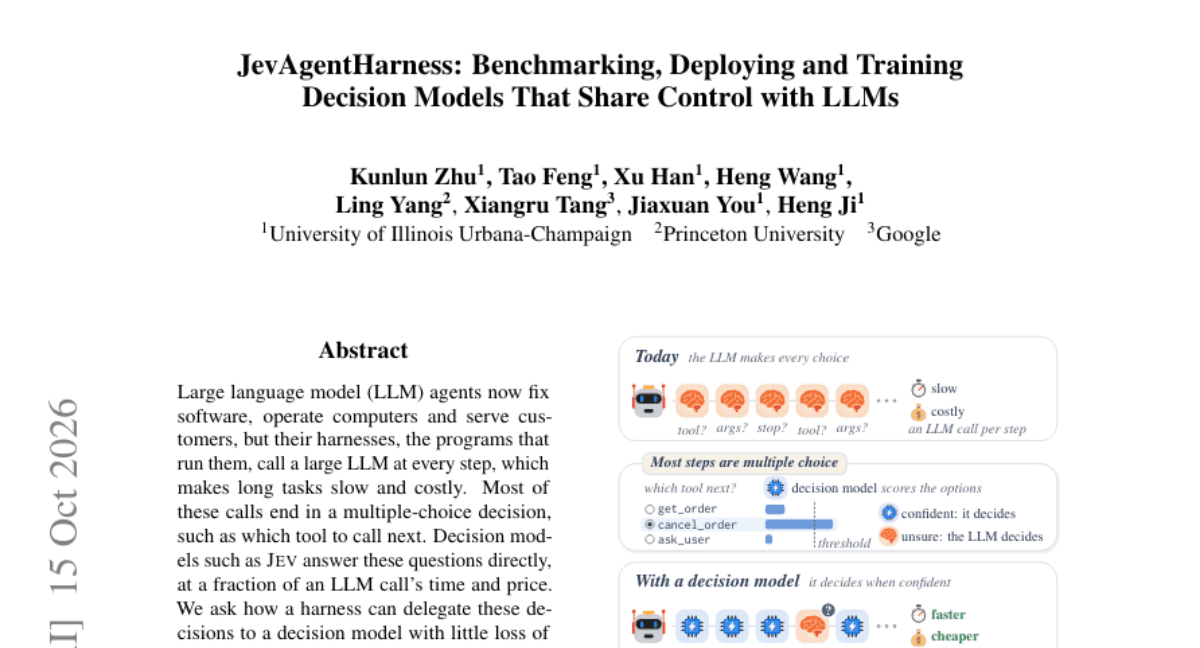
Delegating decisions to the open AgentDecision-4B model cuts agent costs 81.1-89.0% and speeds them up to 2.5x on familiar tasks while keeping success...
China's commerce and science ministries released a draft tightening export controls on 23 AI areas, including frontier models and agents.
Crusoe shows LoRA fine-tuning can keep frozen base weights in 4-bit storage with on-the-fly dequantization, cutting base-weight memory by up to 75%...
QAT improves 2-4 bit model quality yet carries a structural flaw: high-precision latent weights receive gradient updates while loss and gradients are...
Western labs released new open-weight models last week to attract users worried about Chinese systems' security, yet they still trail leading Chinese...