1h ago
Llama 4 Scout Moves to Practical Self-Hosting
- Checkpoints for base, instruction-tuned, and quantized variants now available on Hugging Face Hub and Meta's portal
- Free downloads for local and...
Created by Cheng Niu
Open‑source and flagship AI model releases, benchmarks, safety notes across LLMs, vision, speech, multimodal
Explore the latest content tracked by AI Model Release Tracker
H-JEPA stacks JEPA layers across time scales so high-level plans become low-level subgoals, lifting long-horizon visual planning success from 18% to...
Microsoft quietly uploaded AesCode-32B to Hugging Face on 7 October with zero announcement, a 33B vision-language model that turns prompts into...
OpenAI added gpt-rosalind-discovery to its pricing page under life sciences models next to gpt-rosalind-research, both at $5 per million input and $25...
OrcaRouter released OrcaCyber Zero 1.5 as successor to Zero 1.0, post-trained specifically for vulnerability reproduction, exploit development and...
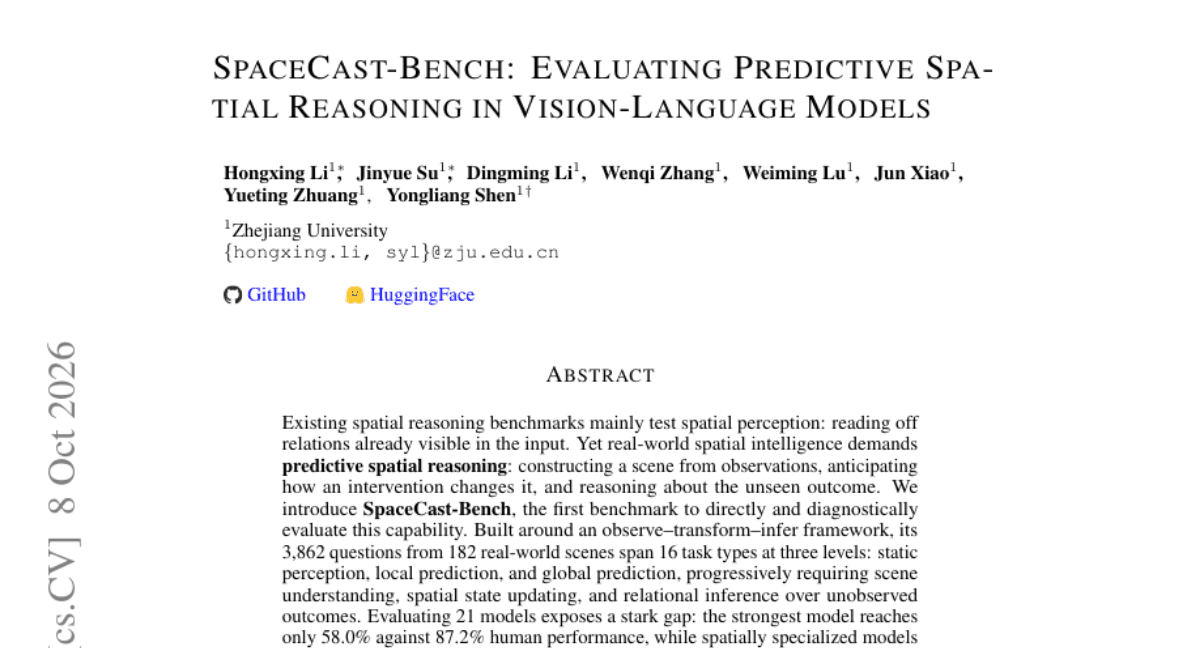
Two new arXiv papers signal a clear shift in VLM research toward predictive spatial reasoning and visual-native skill learning.
Meta Muse Code stands out by prioritizing deep repository access and data capture instead of competing on code-completion quality alone.
Public benchmarks offer too little overlap to declare a coding winner between GPT-5.4 and Beam.
Edda v0.2 large delivers immediate developer value as a fully open Whisper-large-v3 fine-tune for Danish speech recognition, directly loadable via the...
Cloudflare released Clef-omni, an open-weight decision model extending the Clef series to native text, image, audio, and video processing.
Microsoft's Qwen3.5-9B decision model leads a 36-benchmark comparison at 83.5% average accuracy and 85 ms p50 latency, but ships only as a hosted API with no public weights or disclosed hardware.
SuperNav equips a pretrained MLLM with an agent harness that keeps high-level request interpretation, scene understanding, and decision-making inside...
Reflection AI's new Beam model targets coding and tool-use tasks with a focus on lower inference compute.
HeyGen has launched its first in-house voice model, HeyGen Voice, claiming the #1 ranking on ArtificialAnlys for natural, expressive performance. Built for authentic results, it is now available inside the HeyGen product and via API.
JPT-0.8B shows just 6 source-displayable benchmark rows out of 667 tracked slots, all from Decision Index 0.3 categories, with large gaps behind...
Evoke matches a 0.6B dense embedding model on top-100 recall to within 0.004 and finds more relevant results in the top 1,000, all while running on CPUs and directly inside PostgreSQL. The open 30M-parameter model is available today.
Qwen-Image-2.1-Turbo delivers the same 7B visual generator and Qwen3-VL 8B conditioning in an 8-step checkpoint, trading the base model’s 40-step...