August 19, 2026
Cerebras CS-4: 30x GPU Leap Enables Ownable AI Infrastructure
- 30x performance edge: CS-4 delivers up to 30x faster results than GPU systems with 750 PFLOPs across three Wafer Scale Engine 3 Turbo chips.
-...

Created by GrowthMasters Team
A content tracker sharing interesting discoveries
Explore the latest content tracked by Juan || AI GTM Infrastructure Trendjacking (7d)
Leaders must evaluate all seven cost categories to assess total spend when deploying AI agents at scale.
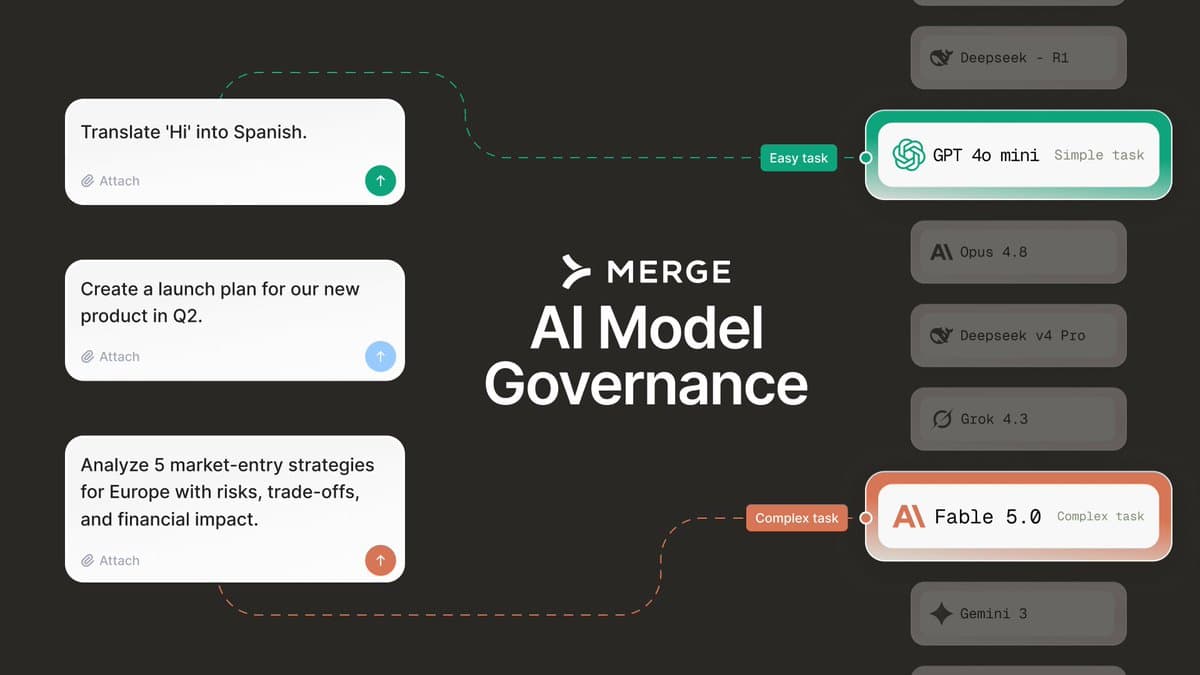
Merge for Workforce cuts AI spend by 75% in one click by routing tasks to cheaper models. Teams otherwise face either 100x overspending on frontier models or subpar outputs.
Both the operator post and Rox launch message frame revenue agents as end-to-end replacements for research, follow-ups, and CRM work.
Qwen 27B matches closed-source SOTA from just months ago and runs on an RTX 5090, labeled a "DeepSeek moment" for open source. This shift supports local deployment and lower vendor lock-in for durable GTM stacks.
Weaviate's Query Agent now explores collections first to auto-detect filter values and numeric stats like mean/median/min/max, enabling natural...
OpenAI pauses frontier model training, creating potential supply constraints for GTM teams reliant on advanced models and underscoring risks of vendor dependency.
IBM's $240 million multi-year pact with Together AI for a dedicated 2,000-GPU NVIDIA B300 inference cluster on IBM Cloud launching Q1 2027 marks the...
AudioCodes Voca CIC became one of the first solutions certified under Microsoft's new Teams Voice Agent Certification Program, extending its existing...
Gemini 3.7 Flash now drives the Spark agent, delivering stronger multi-step automation across Google Workspace for tasks like file consolidation,...
Anthropic's planned $6B acquisition of Decart targets inference optimization and hardware-agnostic performance tuning across Nvidia, Google, Amazon,...
EU AI Act compliance now embeds undetectable watermarks in Claude outputs, automatically flagging AI-generated GTM content even after human edits....
DigitalOcean leads real-time gpt-oss-120b inference at $99/month for 360M input/90M output tokens, beating Together and Fireworks at ~$108. Fireworks...
Writer's Palmyra X6 and model-agnostic harness slash token use by up to 50% on agent tasks by trimming redundant calls in the orchestration layer,...
Microsoft's merged Copilot app gives B2B GTM teams a single interface for sales, marketing, and CS tasks powered by M365 Copilot, while enforcing...
Ultrafast inference at up to 750 tokens/sec via Cerebras lets frontier GPT-5.6 Sol power live GTM workflows like conversational AI, lead routing, and...
Frontier model providers are not neutral platforms. As intelligence commoditizes, they will use your prompts, workflows, and usage patterns to launch...
sales_stack gives Claude Code and Codex direct access to 300M+ profiles for lead generation, enrichment, research, and LinkedIn automation through a...


