2h ago
MoE Efficiency Forces Rethink of GPU Advice
Local hardware guidance stuck on parameter counts misses the real story.
- Dense models demand full VRAM for every parameter, with offloading...
Created by CuratorMaster
Track the open source AI movement: Llama, Mistral, local deployment, fine-tuning, and the community democratizing AI.
Explore the latest content tracked by Open Source AI
Local hardware guidance stuck on parameter counts misses the real story.
Testing LM Studio and Ollama shows a clear split in daily use.
One-click installers and step-by-step tutorials from The Local Lab let creators run image, video, TTS, and LLM tools locally with no config headaches, backed by 69+ workflows and an active community for 6GB+ VRAM hardware.
Microsoft launched Microsoft-Decision-1 based on Alibaba's Qwen3.5-9B open-weight model to enter the constrained decision-model space.
NVIDIA's approach ranks base checkpoints by their expected performance as coding agents after post-training, not raw benchmarks. This matters...
GPT4All lowers barriers to private local AI with one-click installers across Windows, macOS and Linux plus CPU-only inference that runs on modest...
Instruction fine-tuned LLMs deliver higher overall accuracy than BERT baselines for crisis information extraction (63.80% vs 57.67%), showing greater effectiveness in the task.
Token-level routing pushes the cost-quality frontier further than query-level approaches by switching models mid-generation.
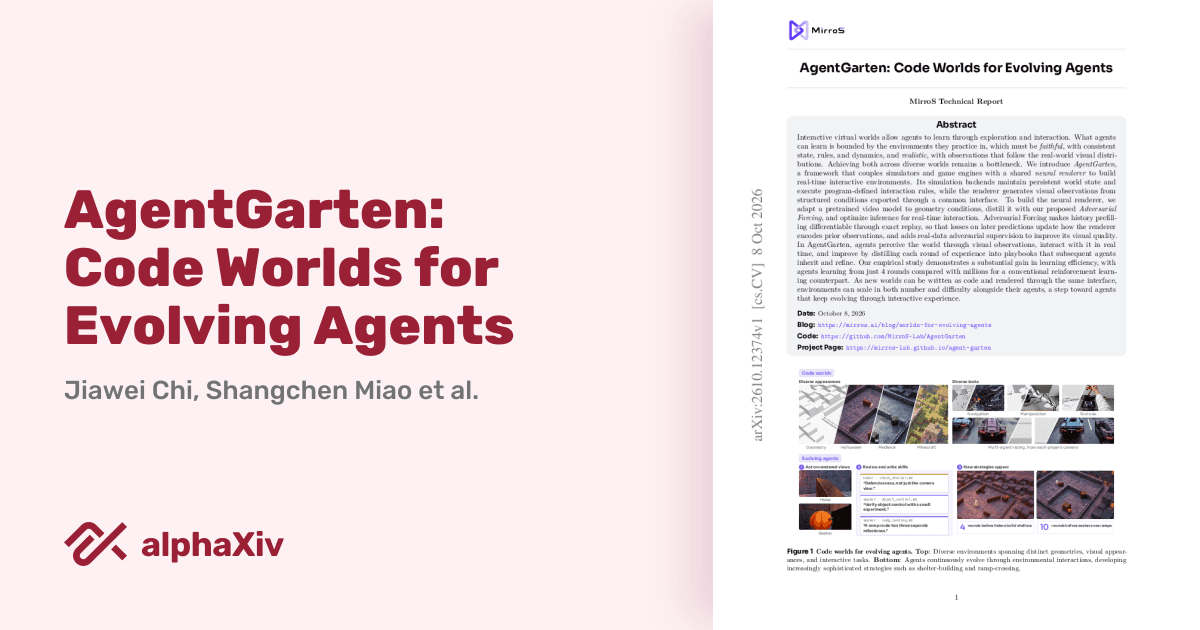
Agent capability is bounded by environments that deliver faithful state and rules alongside realistic visual observations. AgentGarten pairs...
Shared reasoning traces from proprietary LLMs are not harmless debug artifacts. Scraping 315,320 blocks from public repositories yielded 367 PII...
MangoBoost's serverless Mango Inference service now offers production-ready access to open models running on AMD Instinct GPUs with ROCm software....
Old Intel Mac Pros with AMD GPUs can now run local models via ToshLLM's Native Metal acceleration, proving feasibility beyond cutting-edge...
BehaviorBench evaluates frontier models across 20 scenarios and four capabilities to measure their grasp of human behavior.
Fine-tuning a LLaMA-2 backbone with LoRA and style-aware adapters on a seven-language corpus enables LLMs to match diverse journalistic styles while...
LoRA adapters let you adapt EmbeddingGemma to your own documents, product names, or audio events in minutes on a single GPU, updating under 2% of...
Open weights separate models from providers, elevating the operational layer of inference, quantization, and routing as the new competitive edge.
-...
Long-horizon agents force users into oversight roles where final results alone cannot reveal consequential decisions. The Evidence-Grounded Behavior...
Developers weigh these factors when choosing local inference over cloud APIs:
SparseDecoding aligns layer-wise pruning with activations from dense-model autoregressive generation, fixing the distribution shift that hurts...