3h ago
Building an Agent Evaluation Stack Beyond Leaderboards
Leaderboard scores work best at the top of the funnel. A practical stack starts with your own tests.
- Start with tasks you can read: The guide...

Created by Amit Pant
Latest AI research papers, benchmarks, and model releases across NLP, vision, multimodal, robotics
Explore the latest content tracked by AI Research Pulse
Leaderboard scores work best at the top of the funnel. A practical stack starts with your own tests.
The authors ask whether AGI progress could come from pairing a lightweight System-1 predictor with System-2, rather than scaling System-2 alone. Their...
Meta reversed the usual robotics playbook. According to reporting, it started with Muse, its consumer AI agent, and then set out to build a body for...
An AI model can perform well in a test environment yet struggle in real use. Different data, changing conditions, or an unexpected use case can expose...
On-policy RL for LLMs assumes training responses come from the current policy. In practice, an inference engine samples responses while a separate...
Start with end-to-end numbers before you optimize:
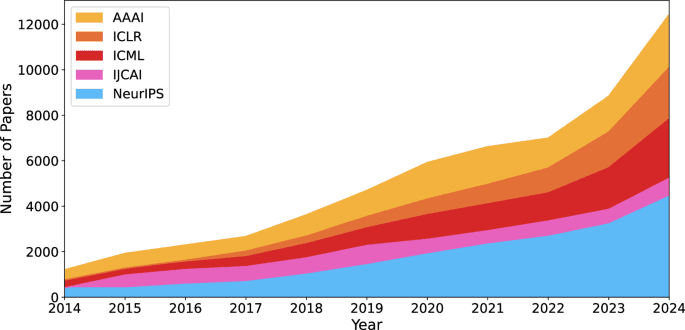
Documentation is improving: papers sharing both code and data rose from 11% to 64% between 2014 and 2024. But that timing complicates the checklist...
For years, CNN-era NPUs were built around maximizing MAC throughput. With LLM and VLM decoding, the limit becomes KV cache access and bandwidth, not...
Robot learning is not only a model-training problem. The quality of the full loop often decides whether an experiment moves beyond a promising demo....
Researchers at Israel's Technion and Sheba Medical Center are applying computer vision and machine learning to breast cancer decisions:
The core problem is that continual parameter updates can trigger catastrophic forgetting, while in-context learning forgets acquired information once...
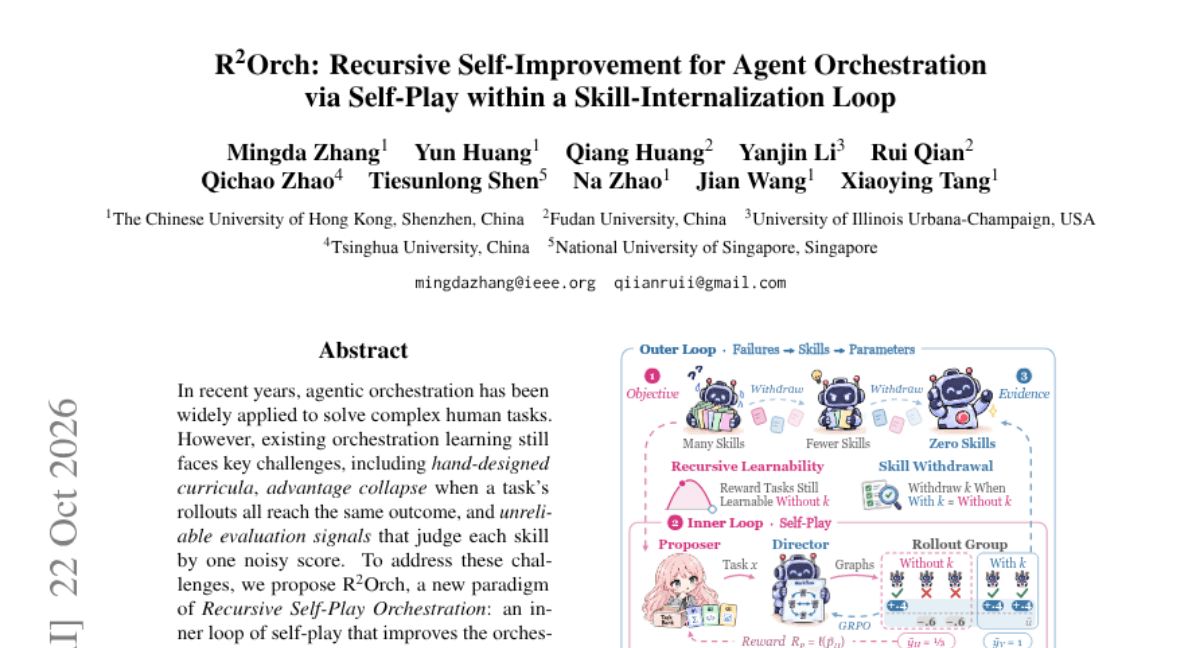
The preprint R$^2$Orch proposes an inner loop of self-play that improves the orchestrator on self-chosen tasks, plus an outer loop that improves how...
A paper from CMU and collaborators argues that pretraining, midtraining, SFT, and RL need not be separate stages. Its unified training runs all of...
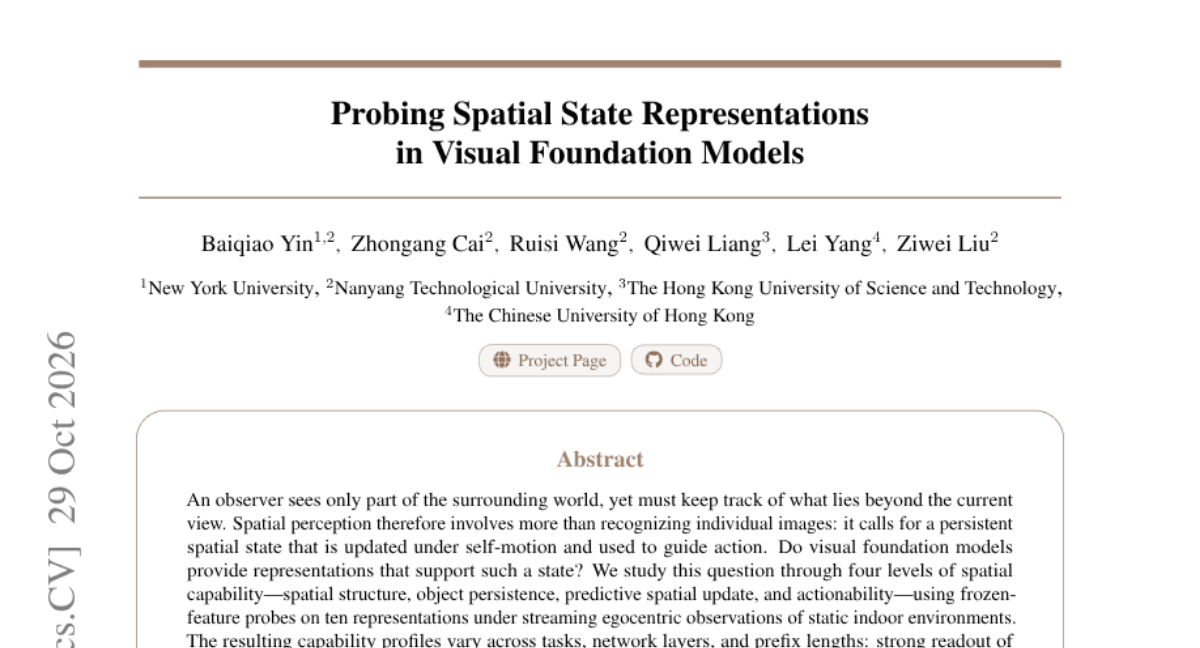
An observer sees only part of a scene, so spatial perception means keeping track of what lies beyond the current view. That calls for a persistent...
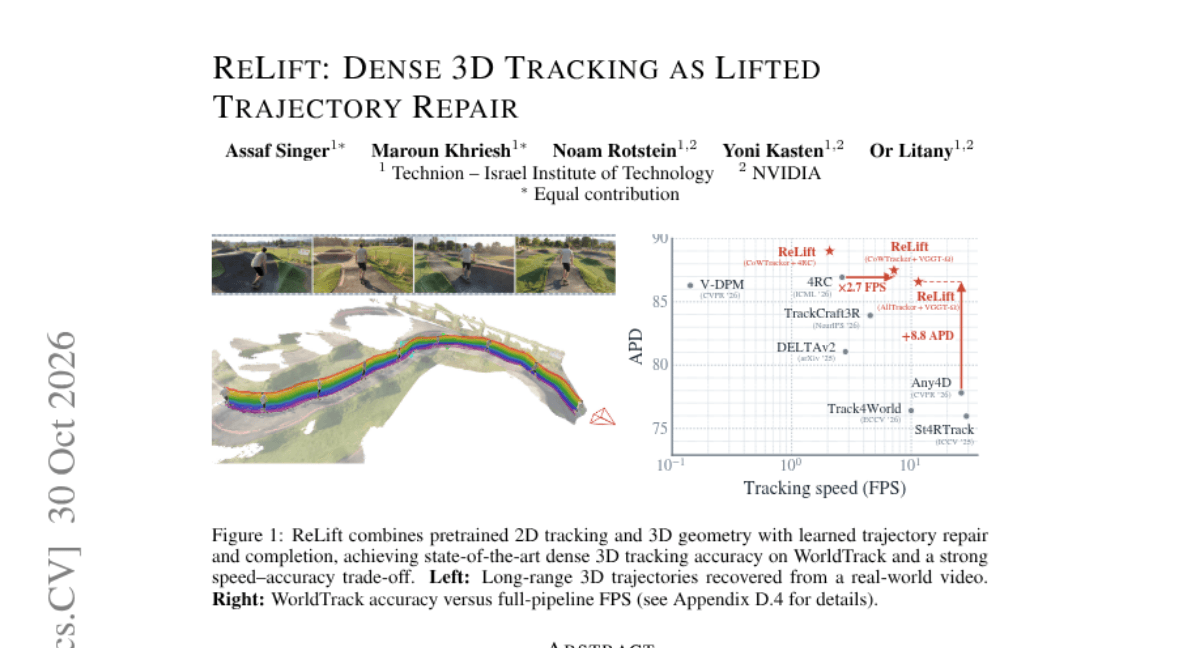
The ReLift paper recasts dense 3D tracking as geometric trajectory repair and completion, rather than learning every task jointly. How it targets...
The paper introduces Wizard, which its authors describe as an agentic game world model for real-time control of character motion. Prior approaches,...
A new writeup claims a default torch.index_add_ call can identify the exact GPU it runs on, even among identical devices.
The idea rests on operation...
Unified image generation must preserve parts of a visual input while following text guidance. Pretrained video models encode visual transformations...
NTU Singapore and Google have signed an MoU to explore AI initiatives across education, research, and workforce readiness. Key elements include:
-...
A repost praises a world-model approach where memory grows as exploration reaches new parts of a scene, while the Gaussians from already built sections are retained. The original poster says Gaussians make a lot of sense for world models.