3h ago
Incidental chatter derails LLM clinical reasoning
Realistic patient notes often contain incidental small-talk and background speech that actively misleads frontier LLMs.
- Models inserted irrelevant...
Created by Xi Cui
LLM release news, benchmark shootouts, tooling, and real‑world AI application insights
Explore the latest content tracked by LLM Benchmark Watch
Realistic patient notes often contain incidental small-talk and background speech that actively misleads frontier LLMs.
Vector steering reveals a low-dimensional manifold behind RLVR gains in LLMs, turning opaque optimization into interpretable geometry.
Two papers highlight parallel requirements for embodied-agent progress: richer spatial world models and guaranteed inference efficiency.
Coding agents introduce supply-chain risks that outpace traditional secure review.
A custom-built agent harness tested on Ian Goodfellow's 2019 "real AI" challenge shows framework design can be decisive for open-ended intelligence benchmarks, beyond the underlying model alone.
Self-reported confidence from heterogeneous models often misleads coordinators: on BigCodeBench, model-mean confidence negatively correlates with...
LLMs fuse five core disciplines to turn text into predictions.
n8n connects the xAI Grok Chat Model to 1000+ apps and services, enabling automated, scalable AI workflows that integrate it directly into technical teams' stacks.
Reverse-KL on-policy distillation reliably transfers compositional reasoning skill across unseen structures but adds almost no new factual knowledge....
Mathematicians are calling OpenAI's reported math results 'pure insanity,' signaling both the potential significance and credibility questions surrounding these performance drops.
A new framework combines LLMs with federated learning to tackle 6G challenges in traffic prediction, resource allocation, and privacy-preserving...
Gemini’s new Map tool lets users drag and zoom a Google Maps view to define a search area, replacing half-remembered street names with a simple Map...
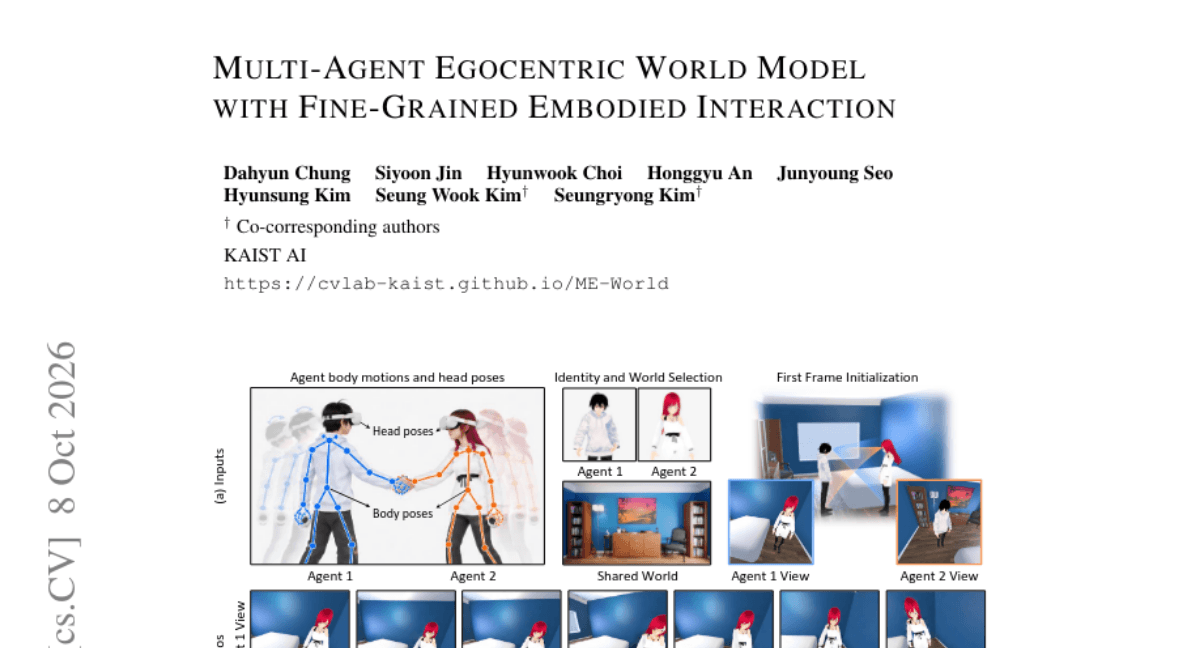
Multi-agent egocentric world models are essential because real embodied environments involve multiple agents interacting via fine-grained actions, a...
OpenAI's push to cut ChatGPT's excessive agreement isn't merely polishing response quality—it's a direct response to documented risks of reinforcing...
Without federal oversight, nonprofits like METR and Transluce are being positioned as critical safety infrastructure for frontier AI labs. Yet funding...
SuperNav delivers strong scene generalization without specialized training, hitting 78% object-search accuracy and 59.5% on demand-driven tasks while...
A fine-tuning approach embeds learnable fingerprints in LLMs for black-box authentication via prompting, enabling model identification and text-origin...
General LLM scores cannot establish clinical reliability or suitability for patient decisions. This task demands specialist evidence instead, as broad benchmarks provide no reliable answer.