50 min ago
Usage Rankings Are a Signal, Not a Scorecard
Live usage rankings are a useful market signal, but the method sets their limits. The board shows DeepSeek leading with 45.4% of usage over a rolling...
Created by Xi Cui
LLM release news, benchmark shootouts, tooling, and real‑world AI application insights
Explore the latest content tracked by LLM Benchmark Watch
Live usage rankings are a useful market signal, but the method sets their limits. The board shows DeepSeek leading with 45.4% of usage over a rolling...
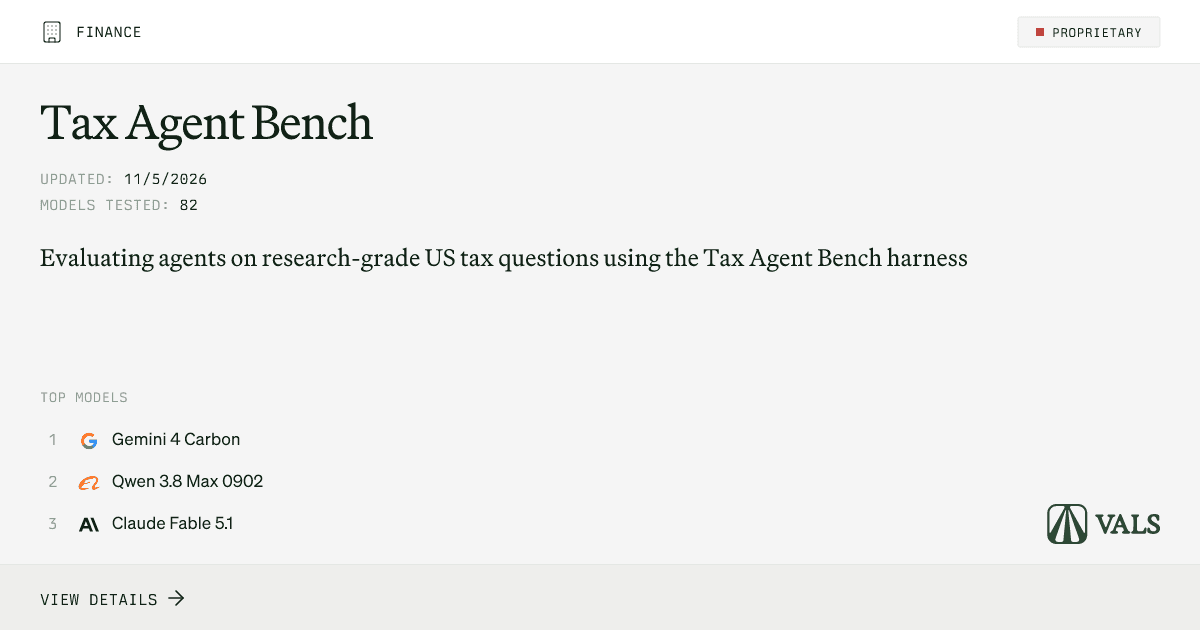
Benchmarks are shifting toward messy, task-specific work, and early results show clear gaps.
Practitioners in this thread say LLMs shine on side projects and legacy code. One describes using them to map behavior, build tests, and rewrite old...
A single leaderboard number is a weak signal on its own. Several sources point the same way:
METR estimates Anthropic's benchmark scores have improved at 1.9 times their earlier rate since October 2025, with a 95% confidence interval of...
Companies are using more AI, but spending on it has leveled off. Here's what the Ramp data suggests:
The most transferable part of Muir is its design: asymmetric gating that compresses the erase gate more than the write gate, with a matched-filter...
Before trusting the rankings, look at how the board measures results:
Per-character prices alone can understate what a voice agent really costs to run. The analysis highlights several factors that change the math:
-...
Dwarkesh says he spent $20,000 in API credits having AI models play each other at Blood on the Clocktower, a Mafia-style social deception game. He...
A new open-source broker takes on a core security question: how can an agent act for you without holding your full credentials? The Agentic Identity...
Model drift means a deployed AI system can decline even though the model itself has not changed. The cause lies outside the model: the data, user...
A Show HN post introduces UUMit, which pitches turning idle machines into model endpoints, with a link to its site.
The post itself gives little...
Lowvram is a CLI tool described as a way to run large AI models on low-VRAM GPUs. It drew 3 Hacker News points and was posted about 7 hours before...
The demo shows the basics working in a browser. Type on the typewriter and the game speaks it back, from a model with 31 million parameters.
Still...
Before ranking AI models, check what each score measures and where it comes from:
Gary Marcus partly disagrees with an earlier take, arguing that recent events (midterms, a correction, rising rates and pushback on an OpenAI IPO)...
@natolambert argues that a lack of good enough benchmarks is a bottleneck, at least for recursive self-improvement described as an intelligence...