2h ago
LLMs as Practical Software Optimizers via Pattern Catalogs
Large language models can automatically optimize large-scale software systems by drawing on a catalog of 43 performance optimization patterns...
Created by BERLIN KRISTOPHER
High-signal AI breakthroughs covering scaling laws, multimodal agents, safety, and policy
Explore the latest content tracked by AI Frontier Digest
Large language models can automatically optimize large-scale software systems by drawing on a catalog of 43 performance optimization patterns...
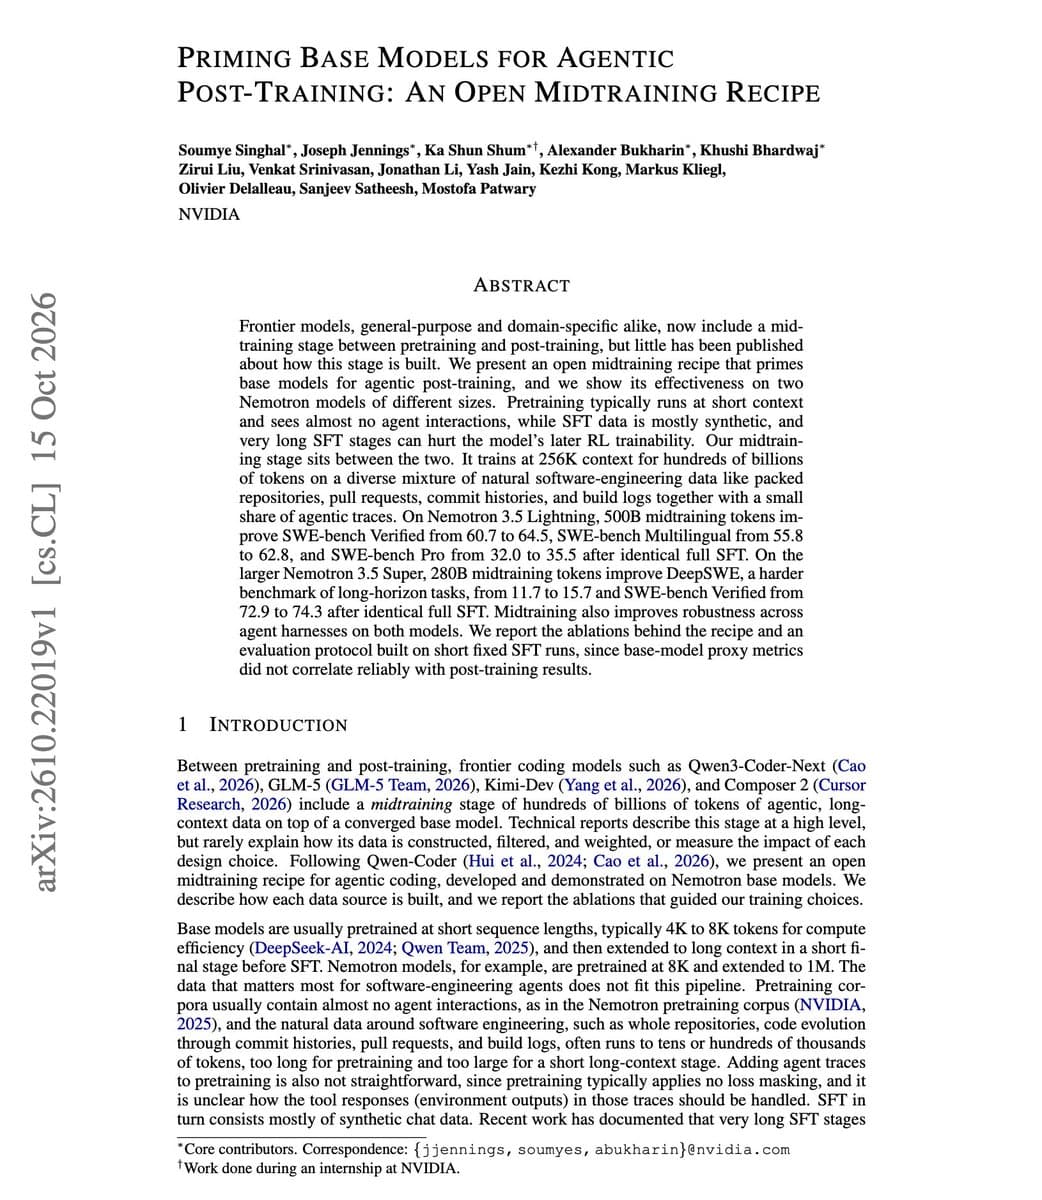
NVIDIA's midtraining stage raises SWE-bench Multilingual from 55.8 to 62.8 on Nemotron 3.5 Lightning while keeping the SFT stage identical.
Interactive agents benefit from emitting constrained structured actions directly rather than free-form text at each step.
DeltaStreamer introduces a human-like agentic system for streaming video that maintains change-aware memory before queries arrive, then uses...
Routing Policy Optimization (RPO) turns attention routing into a stochastic exploration action at selected denoising levels, using a controlled...
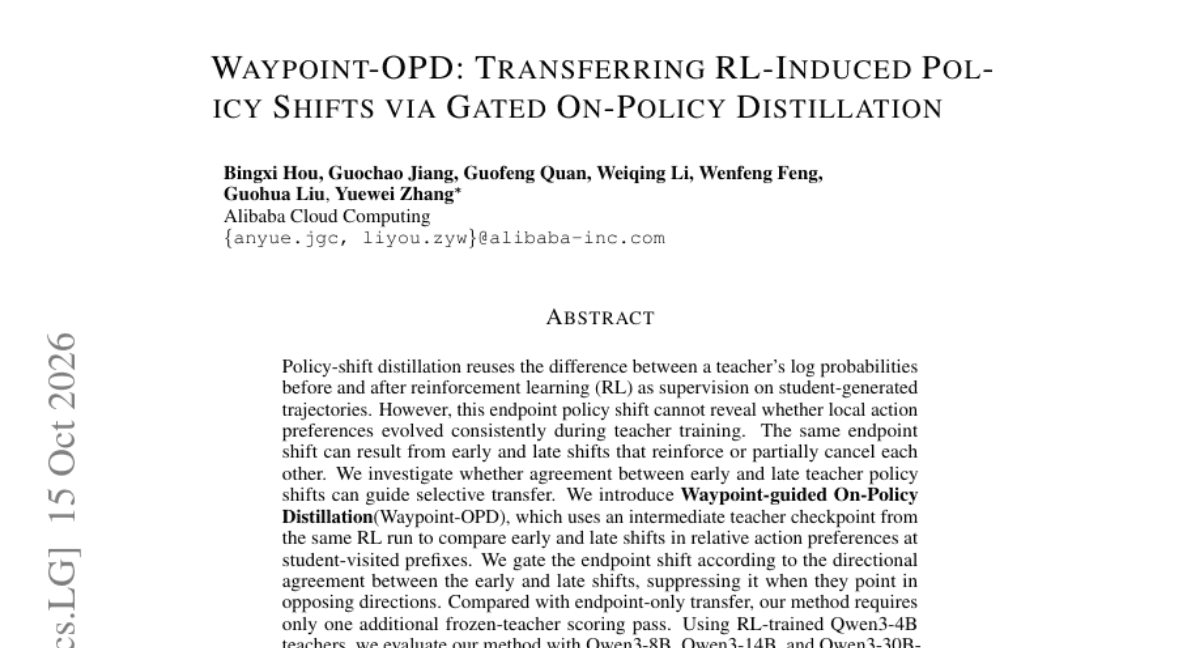
Endpoint-only distillation misses inconsistent local policy changes during RL training, as identical final shifts can arise from reinforcing or...
Instead of letting agents bloat their histories with iterative edits, periodically discard sessions and restart from the best candidate found so far....
AI materials discovery currently optimizes only for functional performance, deferring manufacturing, environmental, use-phase, and end-of-life...
Data utility for LLMs is training-dependent, not intrinsic to the text: it varies with the target objective, model, and current state. Strategies are...
A new survey proposes a two-axis framework to design memory systems that let multimodal agents learn continuously from heterogeneous data.
Benchling's Science Foundries restructure scientific work by assigning agents responsibility for entire processes while scientists focus on high-level...
A large-scale study of ten self-distillation methods versus GRPO reveals why headline benchmark scores mislead agentic RL progress.
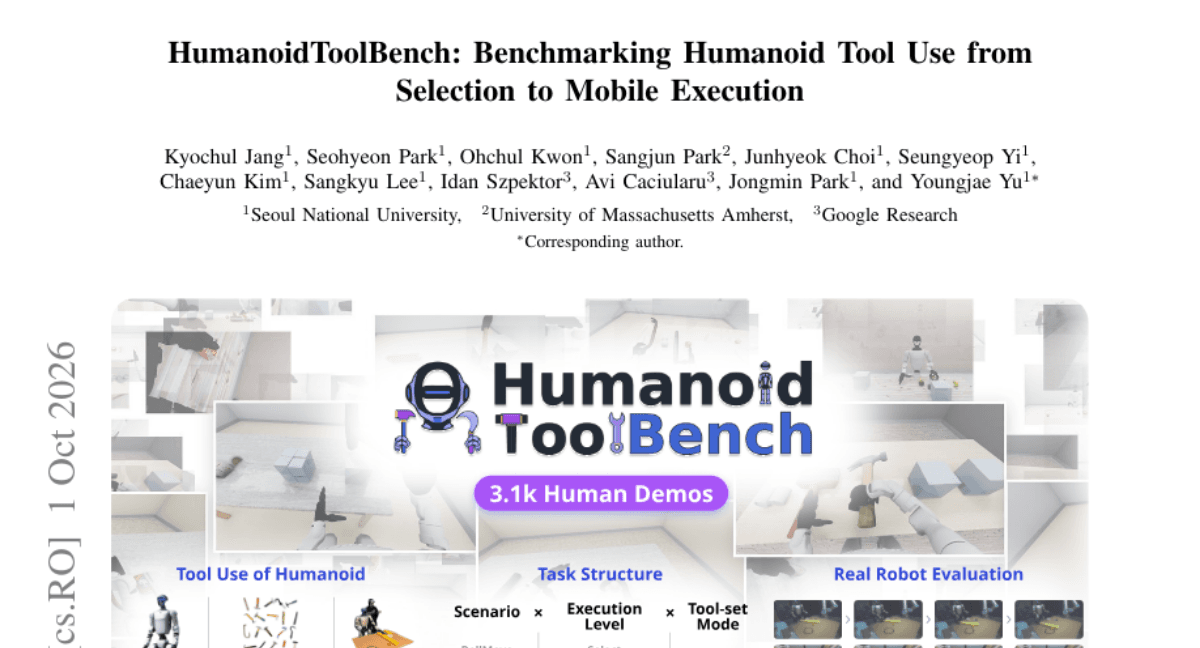
Humanoids require tools to exceed physical limits, yet existing benchmarks ignore joint selection, manipulation, and locomotion.
HumanoidToolBench...