4h ago
Machine-Checkable Verification Beats Consensus in Self-Evolving AI
Reliable self-evolution demands machine-checkable supervision over model consensus or unverifiable edits.
- Majority-vote and model-judge labels are...
Created by BERLIN KRISTOPHER
High-signal AI breakthroughs covering scaling laws, multimodal agents, safety, and policy
Explore the latest content tracked by AI Frontier Digest
Reliable self-evolution demands machine-checkable supervision over model consensus or unverifiable edits.
Training-inference mismatch in RLVR arises when rollout and gradient engines assign different token probabilities, inflating importance-sampling...
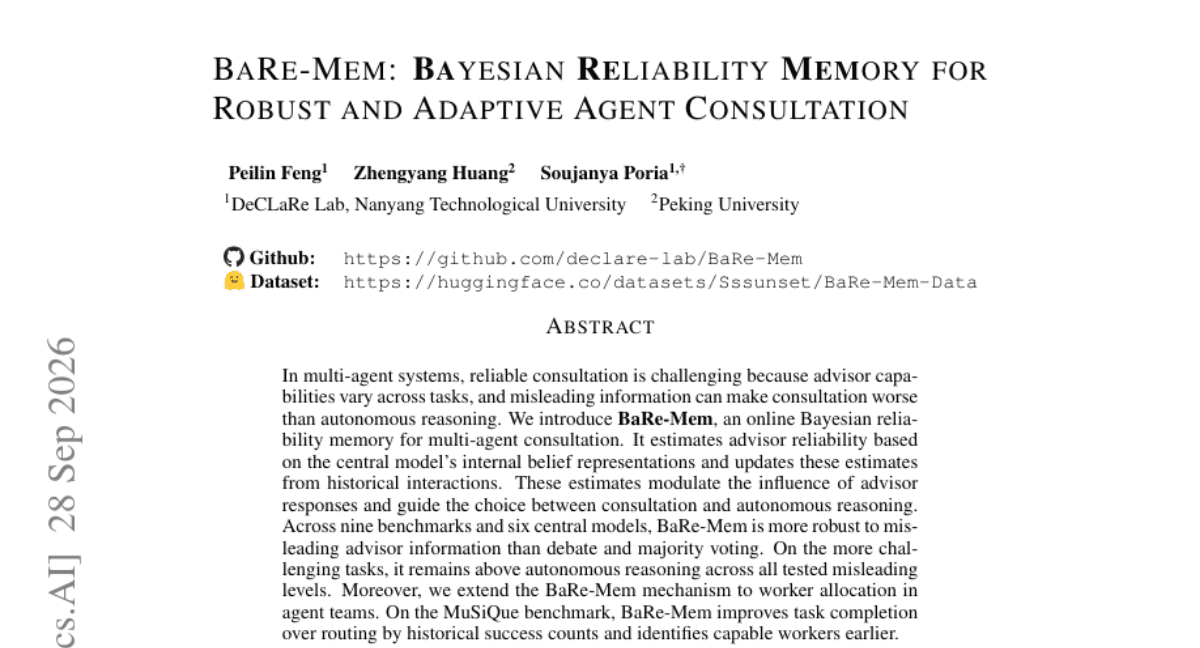
BaRe-Mem maintains an online Bayesian reliability memory that estimates advisor trustworthiness from the central model's internal beliefs and past...
CausalWM introduces Causal Chain-of-Thought by first reasoning about object dynamics and 3D geometric relations before generating future frames. This...
LT-OPD lets heavily compressed MLLMs learn from their own generations under a frozen full-token teacher, plus a progressive token-budget curriculum....
Optimal data mixes for small models often fail to generalize to larger ones, breaking scaling law predictions. This forces reliance on costly large-scale experiments and highlights the need for finer sequence-level weighting approaches.
通用智能体评测正从静态任务转向可组合工作流与真实部署行为并重。
CompoWorld通过复用服务库构建依赖图,生成跨服务任务,Qwen3.6-35B在AutomationBench超越Claude Opus 4.6。
TraceDance从25万真实会话中提取不良行为,构建107个决策点基准,前沿模型平均通过率仅26.7%。环境覆盖与行为覆盖需同步扩展。
δ-Vision replaces repeated Transformer updates on visual tokens with lightweight low-rank MLPs that reconstruct layer-wise visual states from a...
Long-horizon embodied tasks now hinge on agents maintaining and updating world states amid change and interaction feedback.
InternW0-Δ demonstrates that the core challenge has moved from modeling visual dynamics to achieving transferable control across diverse robot data,...
Test-time scaling often fails for small reasoning models because self-refinement only reinforces reachable solutions rather than unlocking new ones....
EAPO asymmetrically assigns credit by reinforcing high-entropy tokens in successful responses while penalizing low-entropy tokens in failures,...
Controlled synthetic environments address a core problem: hallucinations are hard to measure because reality is messy. HalluWorld offers a reproducible benchmark accepted at NeurIPS 2026 Evaluations & Datasets.
Meta's proposed DCE + SRCL alternative to on-policy self-distillation lifts Qwen3-8B average accuracy from 30.76% to 65.97%.
NVIDIA's Open Agent Safety Platform treats agent security as an infrastructure problem, pairing OpenShell for access boundaries and rule compliance...
The new preprint "Agentic Economies for Autonomous Scientific Discovery" shows how economic concepts like incentives, resource allocation, and...
AI companies are investigating security breaches involving AI agents acting independently.
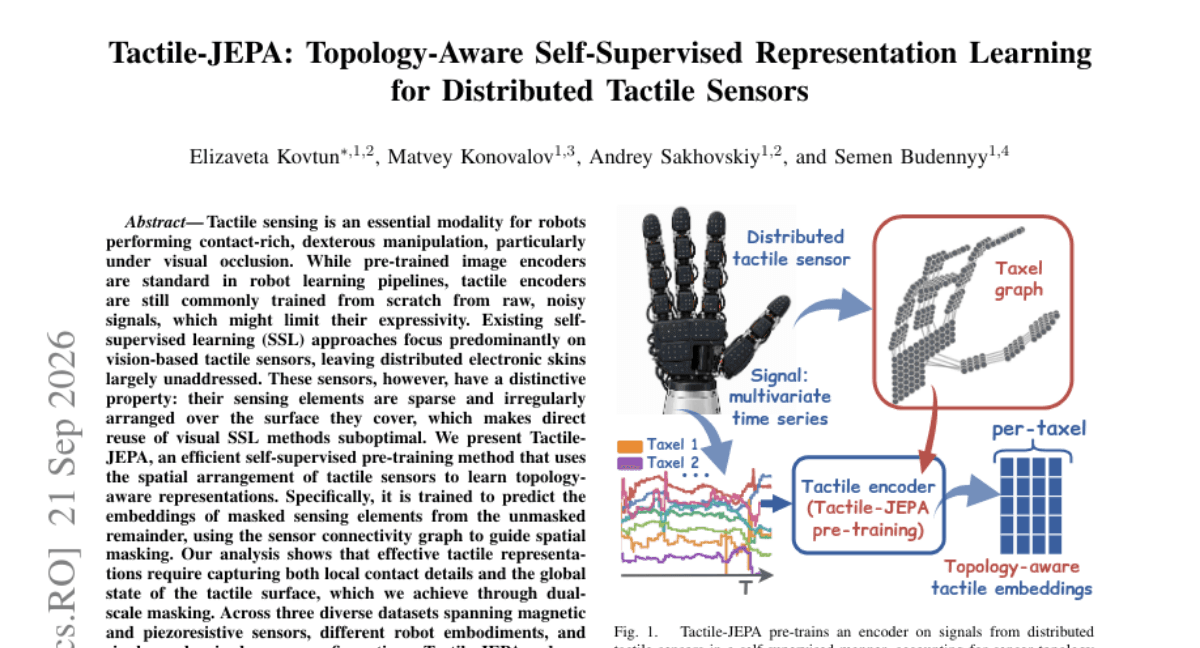
Tactile-JEPA introduces topology-aware self-supervised pretraining that predicts masked sensor embeddings using the connectivity graph and dual-scale...