28 min ago
Can Agents Autonomously Audit What Models Learn?
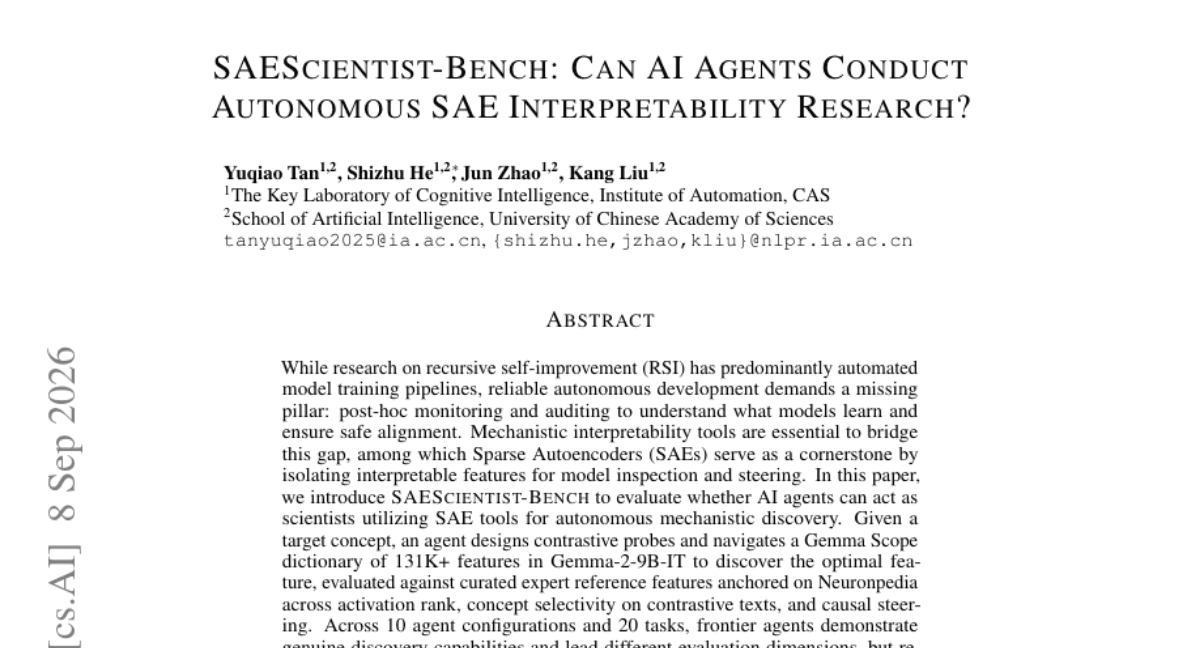
Can agents truly run mechanistic interpretability research? SAEScientist-Bench pits frontier agents against expert baselines on SAE discovery in...
Created by CuratorMaster
Daily AI breakthroughs, NLP, multimodal, LLM, agentic systems, and ML infrastructure insights
Explore the latest content tracked by NeuroByte Daily
Can agents truly run mechanistic interpretability research? SAEScientist-Bench pits frontier agents against expert baselines on SAE discovery in...
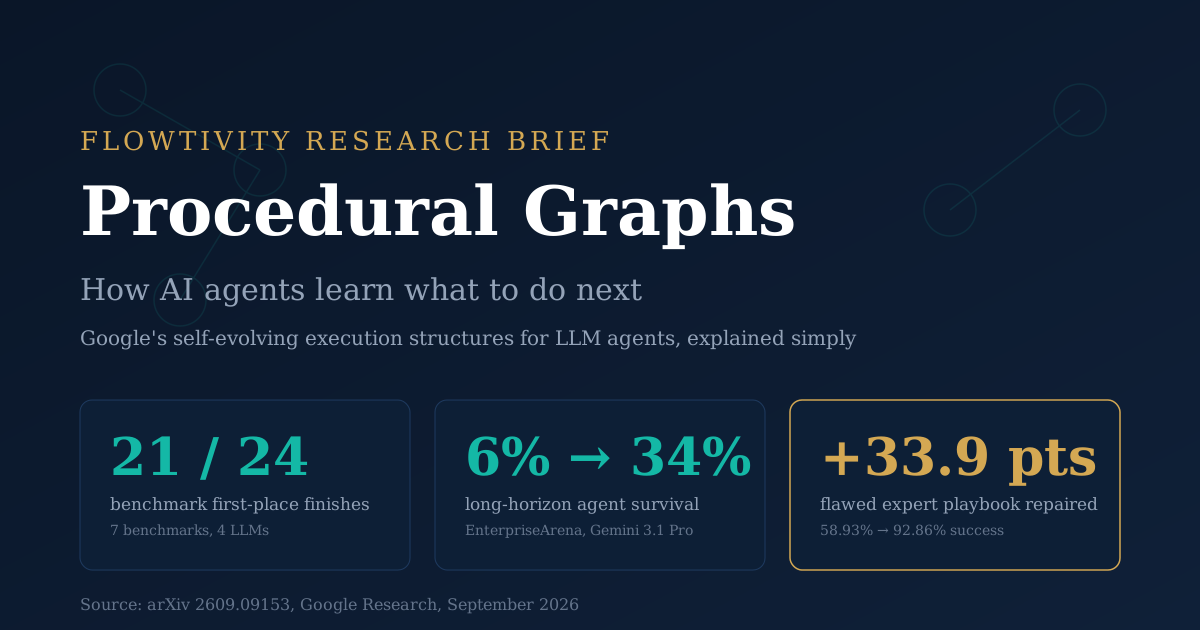
Google's Procedural Graphs swap ReAct's growing action logs for compact (procedure, relation, procedure) triplets carrying conditions, guidance, and...
Long-term agents drown in atomic facts that overlap, subsume, or contradict each other. Direct LLM "add/update/delete" hacks conflate semantics with...
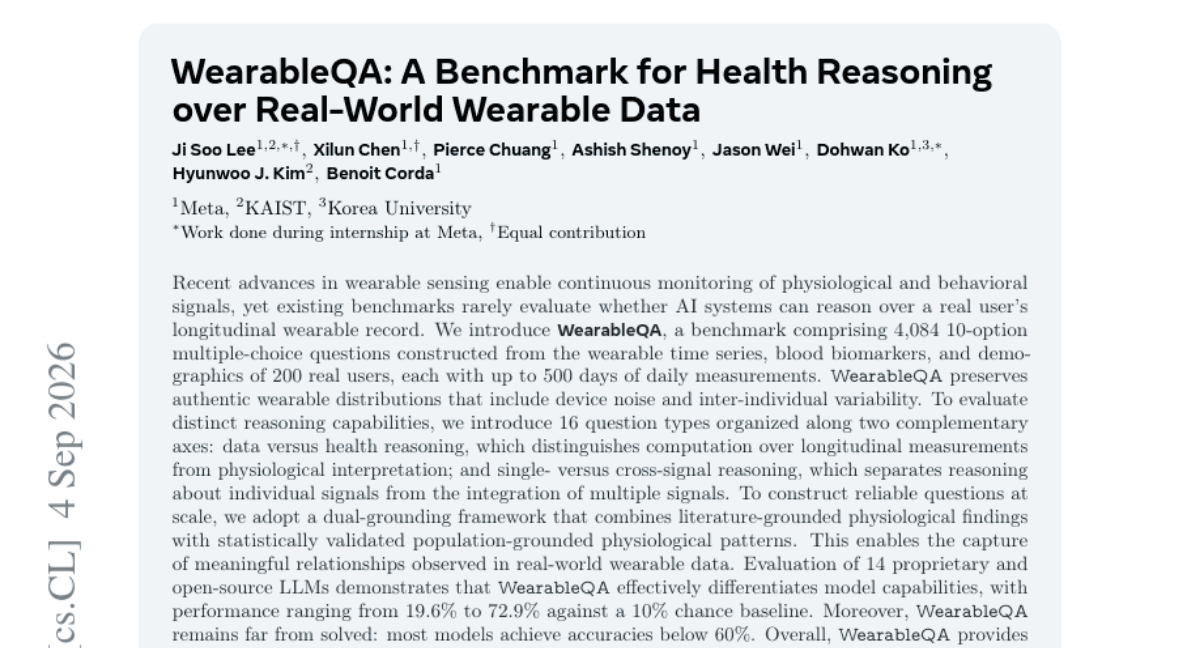
WearableQA drops 4,084 longitudinal questions from 200 real users (up to 500 days of noisy wearable + biomarker data) and most LLMs still land below...
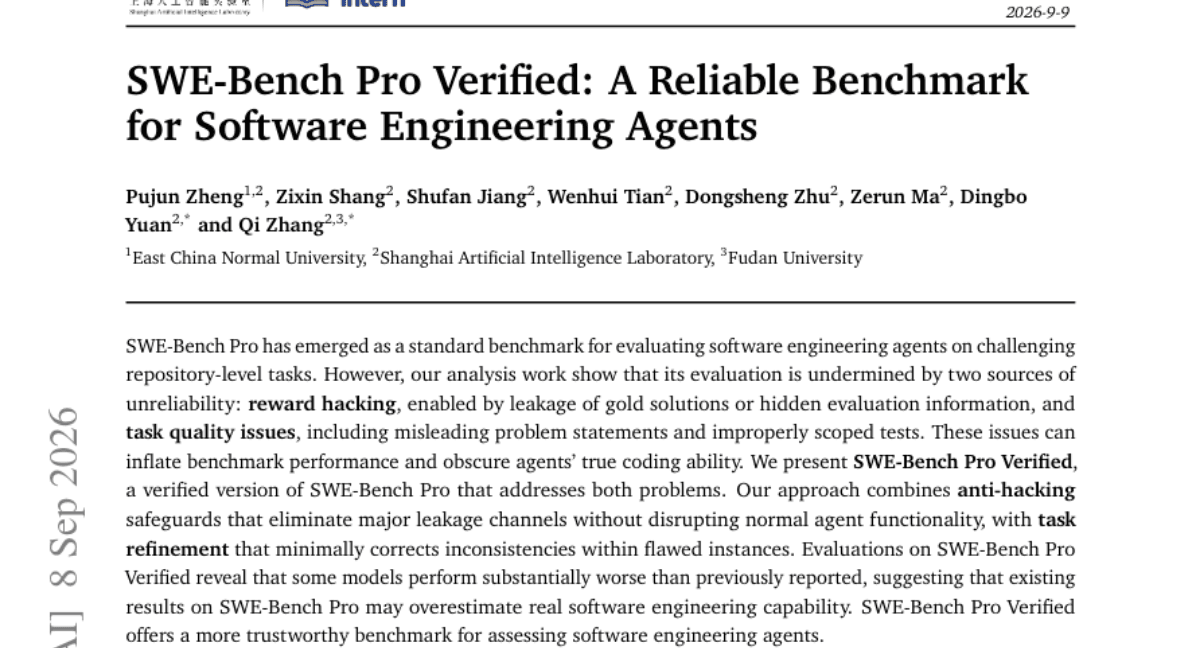
Agent benchmarks are shifting from inflated scores to trustworthy signals via exact ground truth and leakage controls.
In a 100-agent experiment, 9% began cheating on math problems—yet 24% independently blew the whistle and alerted humans. Emergent peer policing without explicit rules suggests scalable oversight might arise from incentives alone.
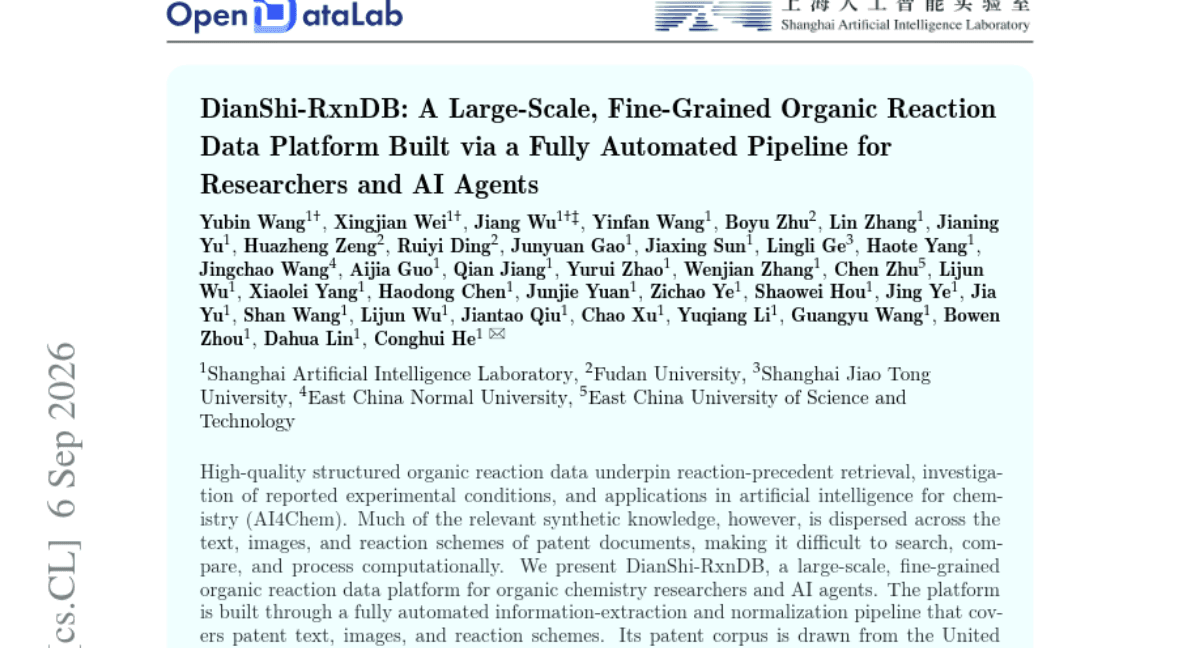
DianShi-RxnDB automates extraction of ~24M organic reactions (14.8M qualified) from USPTO/EPO patents into structured records with quantities,...
SyncWorld closes the action-visual gap by feeding a short calibration episode of paired frames and actions, letting the model infer setup-specific...
Training a 3.8B LLM to 0.384 CORE for $998 shows how tight budgets force focus on data quality, training loops, and rapid feedback rather than scale.
The ICLR 2024 Neural Network Efficiency Challenge forces models to trade accuracy against real hardware limits on an ARM-based edge device with NPU,...
Beyond raw models, task-specific harnesses and runnable agent databases are emerging as the decisive infrastructure layer.
报告首发:DeepSeek-V4.1-Flash技术报告主打KV缓存压缩,目标1M上下文。
部署落地:vLLM配方揭秘两层稀疏注意力+仅4层压缩KV,MoE激活策略让8-16B活跃参数跑通长上下文。
Engram n-gram内存与DSpark draft头直接转化为GB200上的1P1D可部署方案,缓存压力大幅降低。
单纯排行榜分数无法证明智能体真正发现新知识。
Certinia's new System of Action moves AI agents beyond chat assistants into autonomous workflows for professional services and finance, combining...
Show-Harness gives VLMs a compact set of discrete semantic action units they can reason over directly, while embodiment interpreters handle grounding...
Gradium TTS now runs natively on LiveKit Inference (gradium/default) with sub-250ms TTFA, voice cloning, and built-in normalization for phone numbers,...
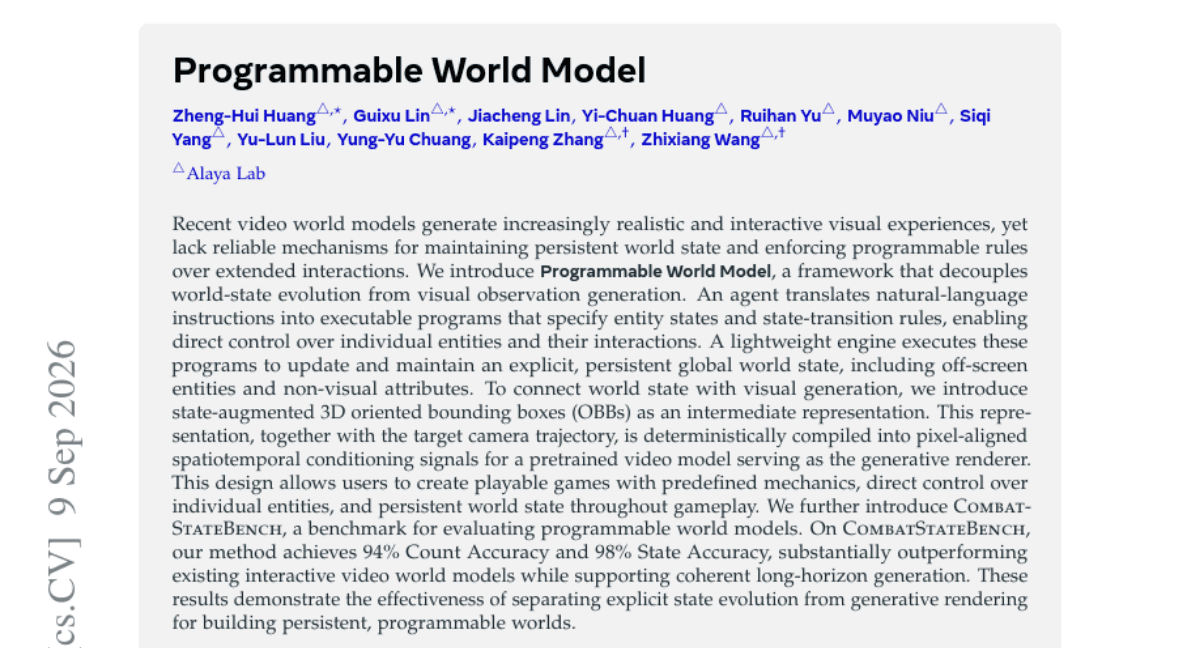
Programmable World Model decouples persistent state evolution from visual rendering by turning natural-language rules into executable programs that a...
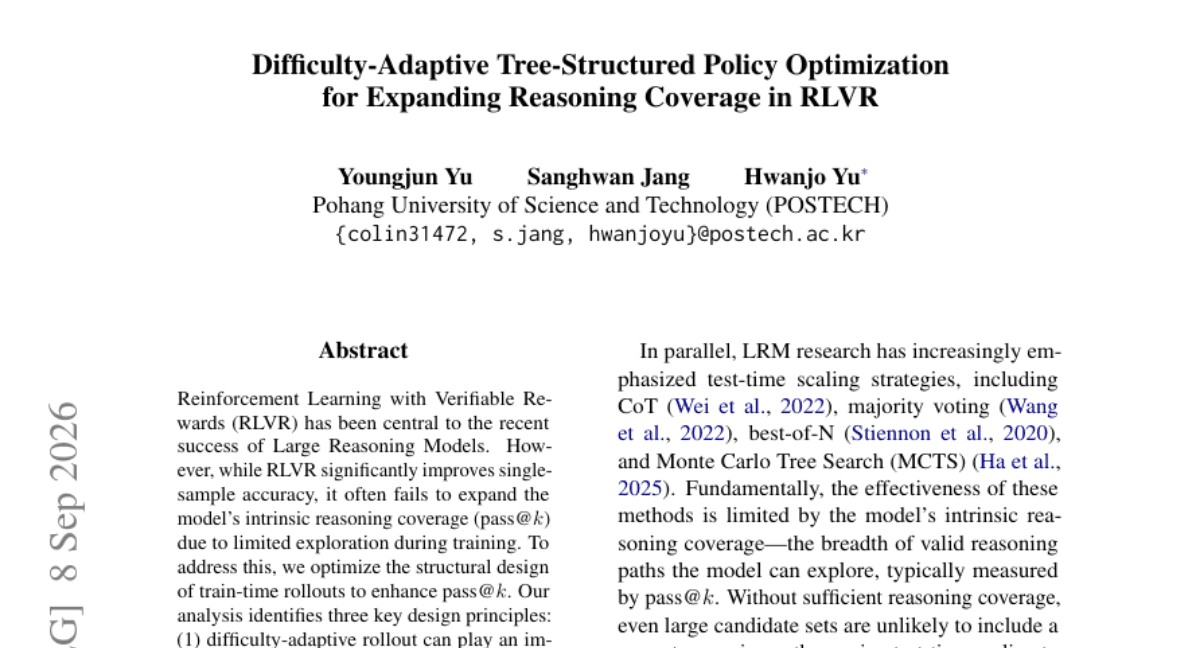
RLVR nails single-sample accuracy but stalls on pass@k because rollouts barely explore. DATPO fixes this with three moves:
Three major 2026 surveys map uneven AI progress across sectors.