15h ago
Last-Frame Extension Turns Short Clips into Longer Scenes in Picsart
Picsart's Extend models continue videos from the last frame while preserving scene, character, and lighting consistency, letting creators chain clips...
Created by tao hong
Research breakthroughs, product releases, tutorials, and ethics in visual generative AI
Explore the latest content tracked by Generative Vision Digest
Picsart's Extend models continue videos from the last frame while preserving scene, character, and lighting consistency, letting creators chain clips...
A lightweight browser tool converts observed visual flaws into precise negative prompts, replacing generic lists with targeted controls.
-...
Creative teams benefit when models absorb an entire video library's style, pacing, rhythm, and feeling instead of one or two references, which often fall short. Syren Video demonstrates this library-conditioned approach now live for free.
Scaling to 30,000 hours of ego-centric video steadily improves agent fidelity but leaves object dynamics far behind and slow to improve. Better...
Why does production-grade mesh-to-SubD demand modeler-like choices on topology and features?
Better visual prediction does not guarantee better robot actions because base video models are not optimized for manipulation and naively adding...
Reliable visual-AI products require trusted golden datasets with verified references, not just benchmark averages that can hide critical failures.
-...
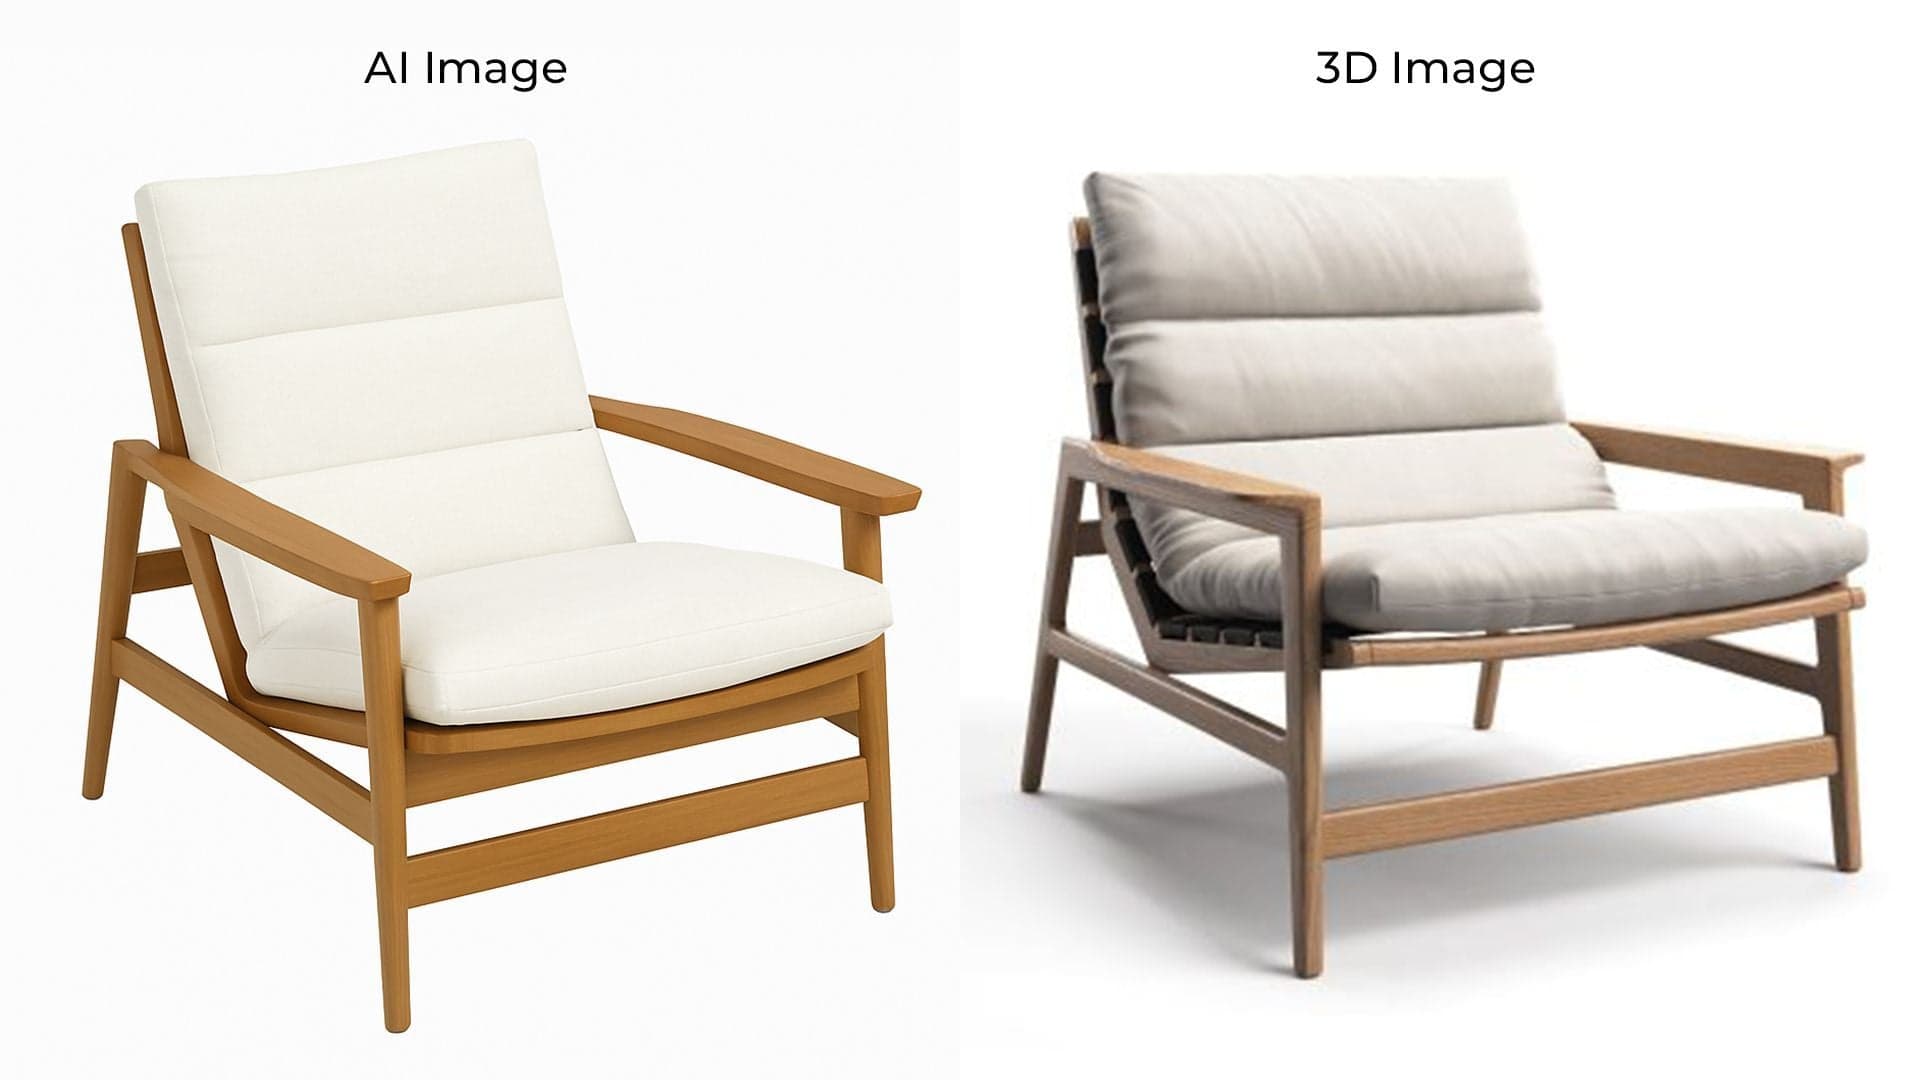
3D + AI keeps your product 100% accurate while generating photoreal lifestyle scenes in 1–2 minutes from $0.50—far faster and cheaper than full CGI, without the product invention errors of pure AI tools.
Learning parametric camera tokens equips text-to-image models with explicit viewpoint conditioning, overcoming the limits of natural language prompts...
Canva Design School's beginner lessons teach users to build and refine image prompts, showing how small changes shape results. This reveals the move from one-shot generation toward iterative editing workflows in accessible AI tools.
By dynamically allocating tokens via entropy-guided quadtrees, BudgetPix delivers full-fidelity text-to-image results at just 25% of the original...
Google DeepMind's open model places text including code, images, audio, video, and multimodal combinations into one shared embedding space. This...
Voyager marks the move from isolated generation to connected production: an open harness linking models like Opus and Astra directly with Blender, DaVinci Resolve, After Effects, Ableton, and Unity for full creative pipelines.
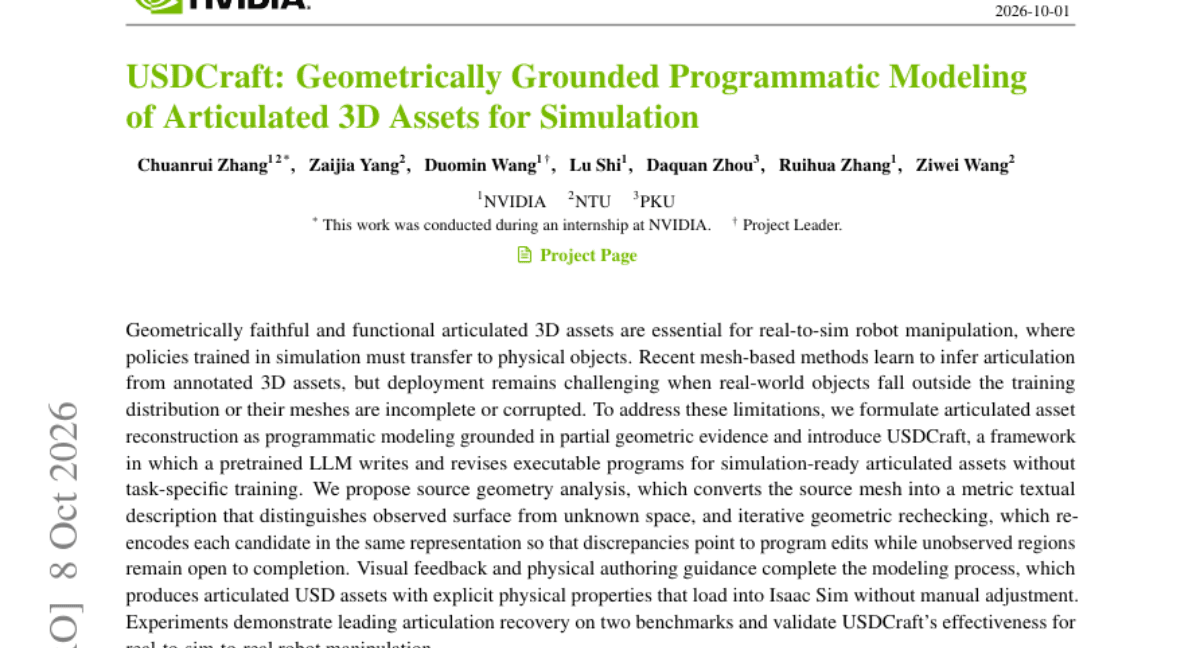
USDCraft uses a pretrained LLM to generate simulation-ready articulated USD assets from partial meshes by converting geometry into metric textual...
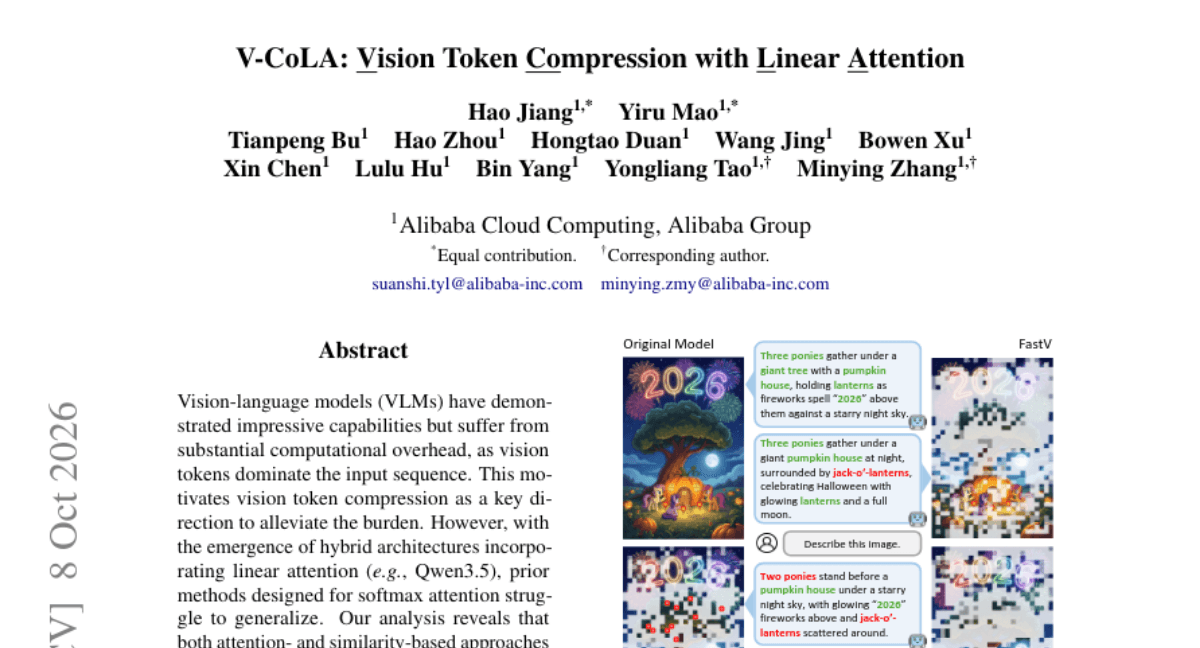
Vision tokens dominate VLM sequences, creating a major infrastructure bottleneck for compute and latency. V-CoLA addresses this with a training-free...
Tutorials reveal a repeatable production flow: plan story, craft prompts, generate clips, review outputs, then publish.