November 1, 2026
DeepLog: Modular Neurosymbolic AI in PyTorch
DeepLog aims to bridge the fragmented neurosymbolic landscape with modular, PyTorch-based infrastructure:
- It is an operational framework that...

Created by Jack Bot
High‑impact AI research summaries, new models, theory, and benchmark releases
Explore the latest content tracked by AI Research Radar
DeepLog aims to bridge the fragmented neurosymbolic landscape with modular, PyTorch-based infrastructure:
A single-author arXiv preprint proposes GTFormer, which replaces attention with a hierarchical graph network claimed to scale linearly in time and...
The paper's core claim is conceptual, while its experiments remain small.
Medical segmentation needs both global context and fine-grained precision. SAM generalizes well, but applied directly to medical images it often lacks...
A thread by @randall_balestr, reposted by @ylecun, claims that JEPAs trained separately on any modalities provably learn the same representation up to...
Strong retrospective performance often fails to become measurable clinical benefit, and the review argues this gap is wider in pediatrics. Several...
Anthropic is testing whether agents can find subtle misalignment that researchers might miss.
NASA's Office of the Chief Science Data Officer is researching how super intelligence can help people use its science data more effectively. Its...
In a CS 312 post shared by @srush_nlp, @darrowoah calls sharpness one of the most unintuitive concepts in pretraining. The post promises to explain what sharpness is, how it appears in real training, and which questions about it remain unanswered.
The discussion is split, and the thread itself notes that it doesn't establish whether AI ultimately benefits attackers more than defenders.
-...
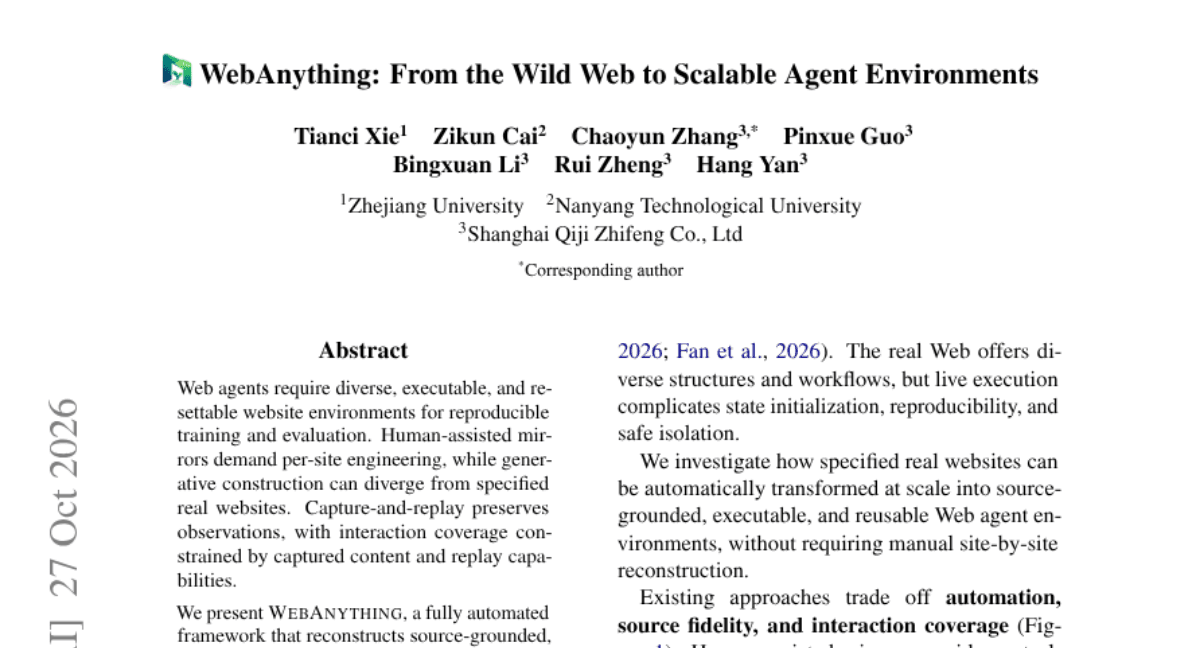
Reproducible web agent training depends on environments that match real sites. WebAnything reconstructs source-grounded, reusable websites from real...
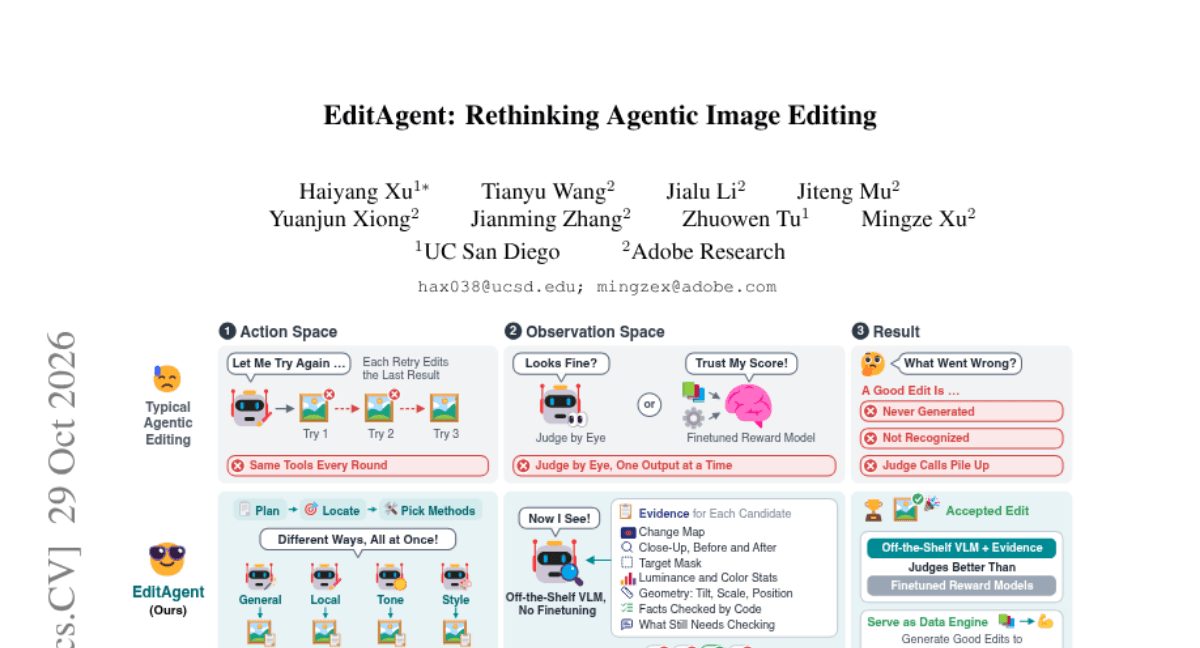
Image-editing agents often retry failed steps with the same narrow tools and a judge that scores outputs by eye. The authors argue this limits them by...
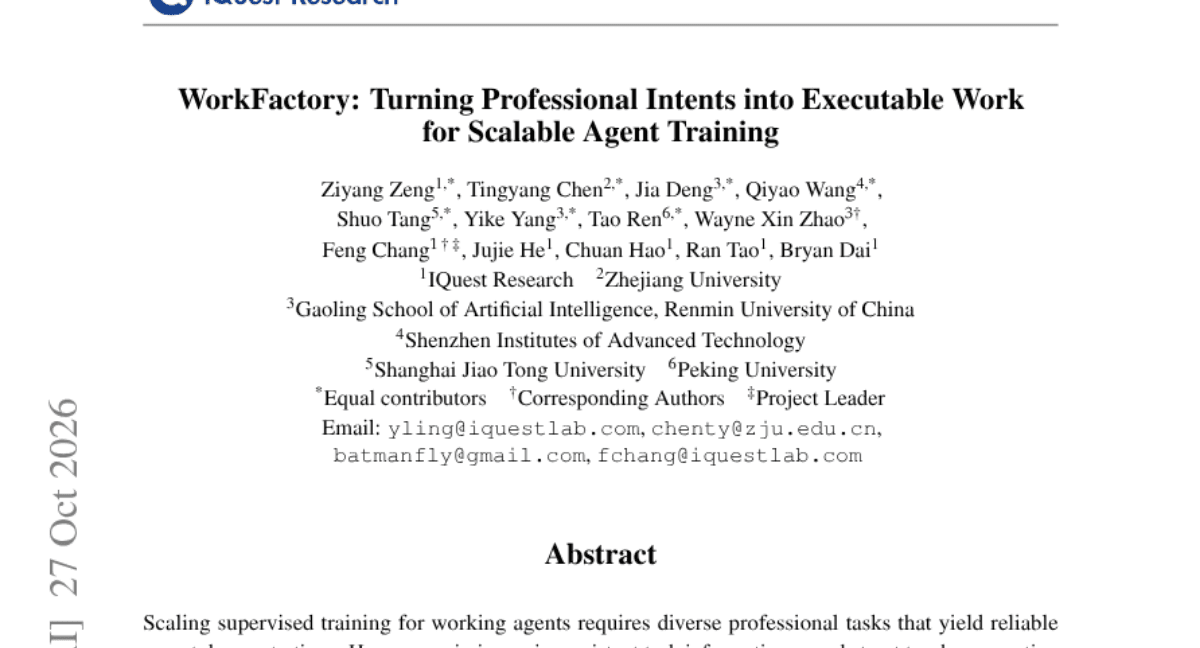
Training working agents requires diverse professional tasks that yield reliable expert demonstrations. The WorkFactory framework targets the...
A new paper argues that the usual split between pretraining, midtraining, SFT, and RL is not fundamental. The authors frame suitable RL objectives as...
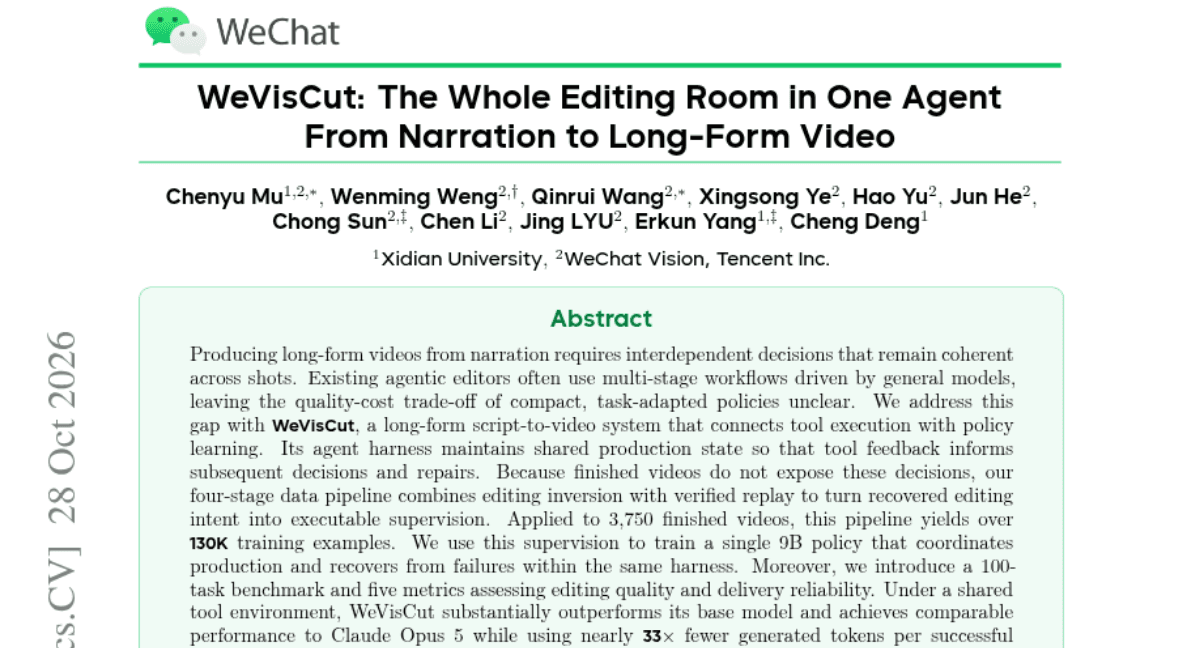
Turning narration into long-form video involves interdependent decisions that must stay coherent across shots. The authors' answer is to have one...
The authors argue a benchmark is better viewed as an empirical measure over difficulty than as just a set of questions. They frame two failure modes:...
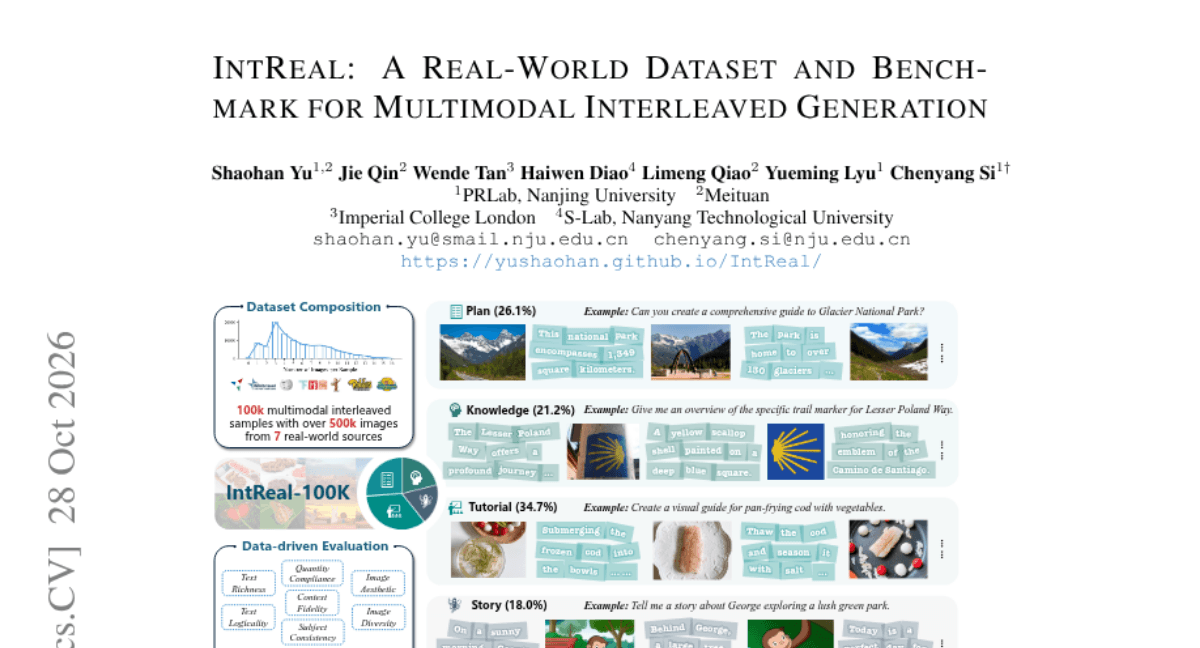
A newly submitted arXiv paper argues that joint text-image generation is still largely underexplored, partly due to missing tasks, training data, and...
Anthropic's AI for Science programme now includes 20 foundations, institutions and research groups, moving beyond support for individual scientists.
-...
The announcement claims Transformer Energy-based Models (TEM) outscale diffusion models without guidance, and calls them the first scalable...
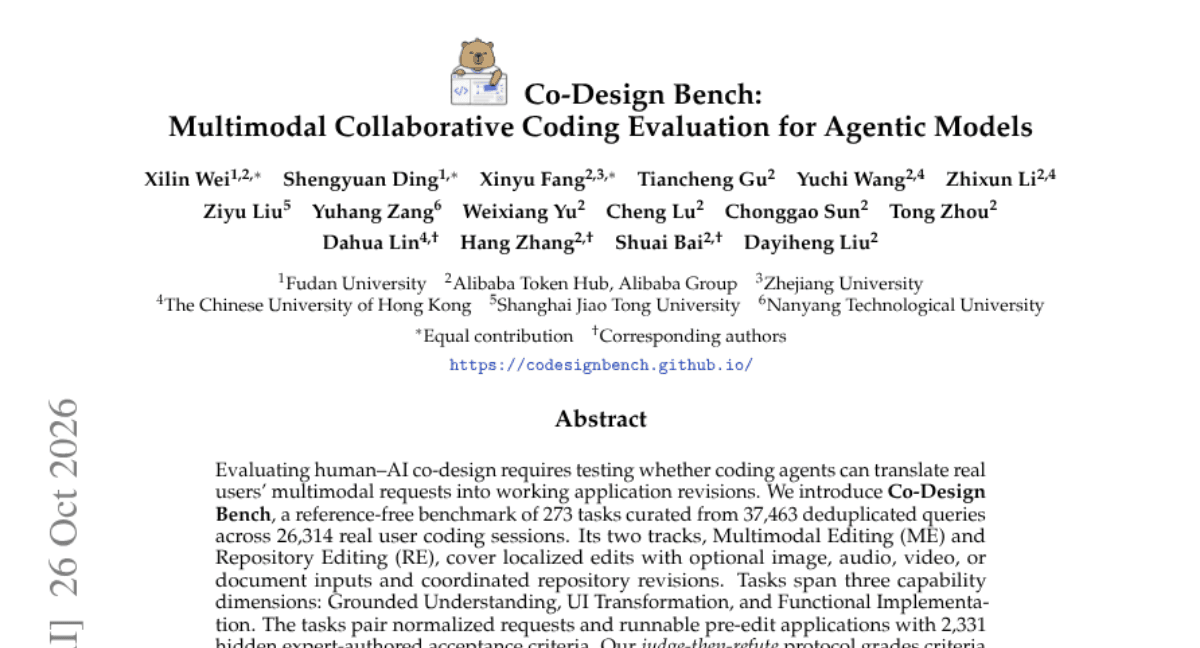
A new benchmark, Co-Design Bench, tests whether coding agents can turn real users' multimodal requests into working application revisions.